Full Text Search
Full text search retrieves documents that contain the terms or phrases in your query and ranks the results by relevance. It complements semantic search, which can overlook precise terms, and is especially useful in retrieval-augmented generation (RAG) scenarios, where documents that closely match specific search terms matter most.
With full text search, you can also skip embedding models: you provide raw text, and Zilliz Cloud converts it into sparse embeddings automatically.
By integrating full text search with semantic-based dense vector search, you can enhance the accuracy and relevance of search results. For more information, refer to Hybrid Search.
Zilliz Cloud supports enabling full text search programmatically or via the web console. This page focuses on how to enable full text search programmatically. For details about operations on the web console, refer to Manage Collections (Console).
BM25 implementation
Zilliz Cloud implements full text search with the BM25 relevance algorithm, a widely adopted scoring function in information retrieval systems, and integrates it into the search workflow to deliver accurate, relevance-ranked text results.
Full text search in Zilliz Cloud follows the workflow below:
-
Raw text input: You insert text documents or provide a query using plain text, no embedding models required.
-
Text analysis: Zilliz Cloud uses an analyzer to process your text into meaningful terms that can be indexed and searched.
-
BM25 function processing: A built-in function transforms these terms into sparse vector representations optimized for BM25 scoring.
-
Collection store: Zilliz Cloud stores the resulting sparse embeddings in a collection for fast retrieval and ranking.
-
BM25 relevance scoring: At search time, Zilliz Cloud applies the BM25 scoring function to compute document relevance and return ranked results that best match the query terms.
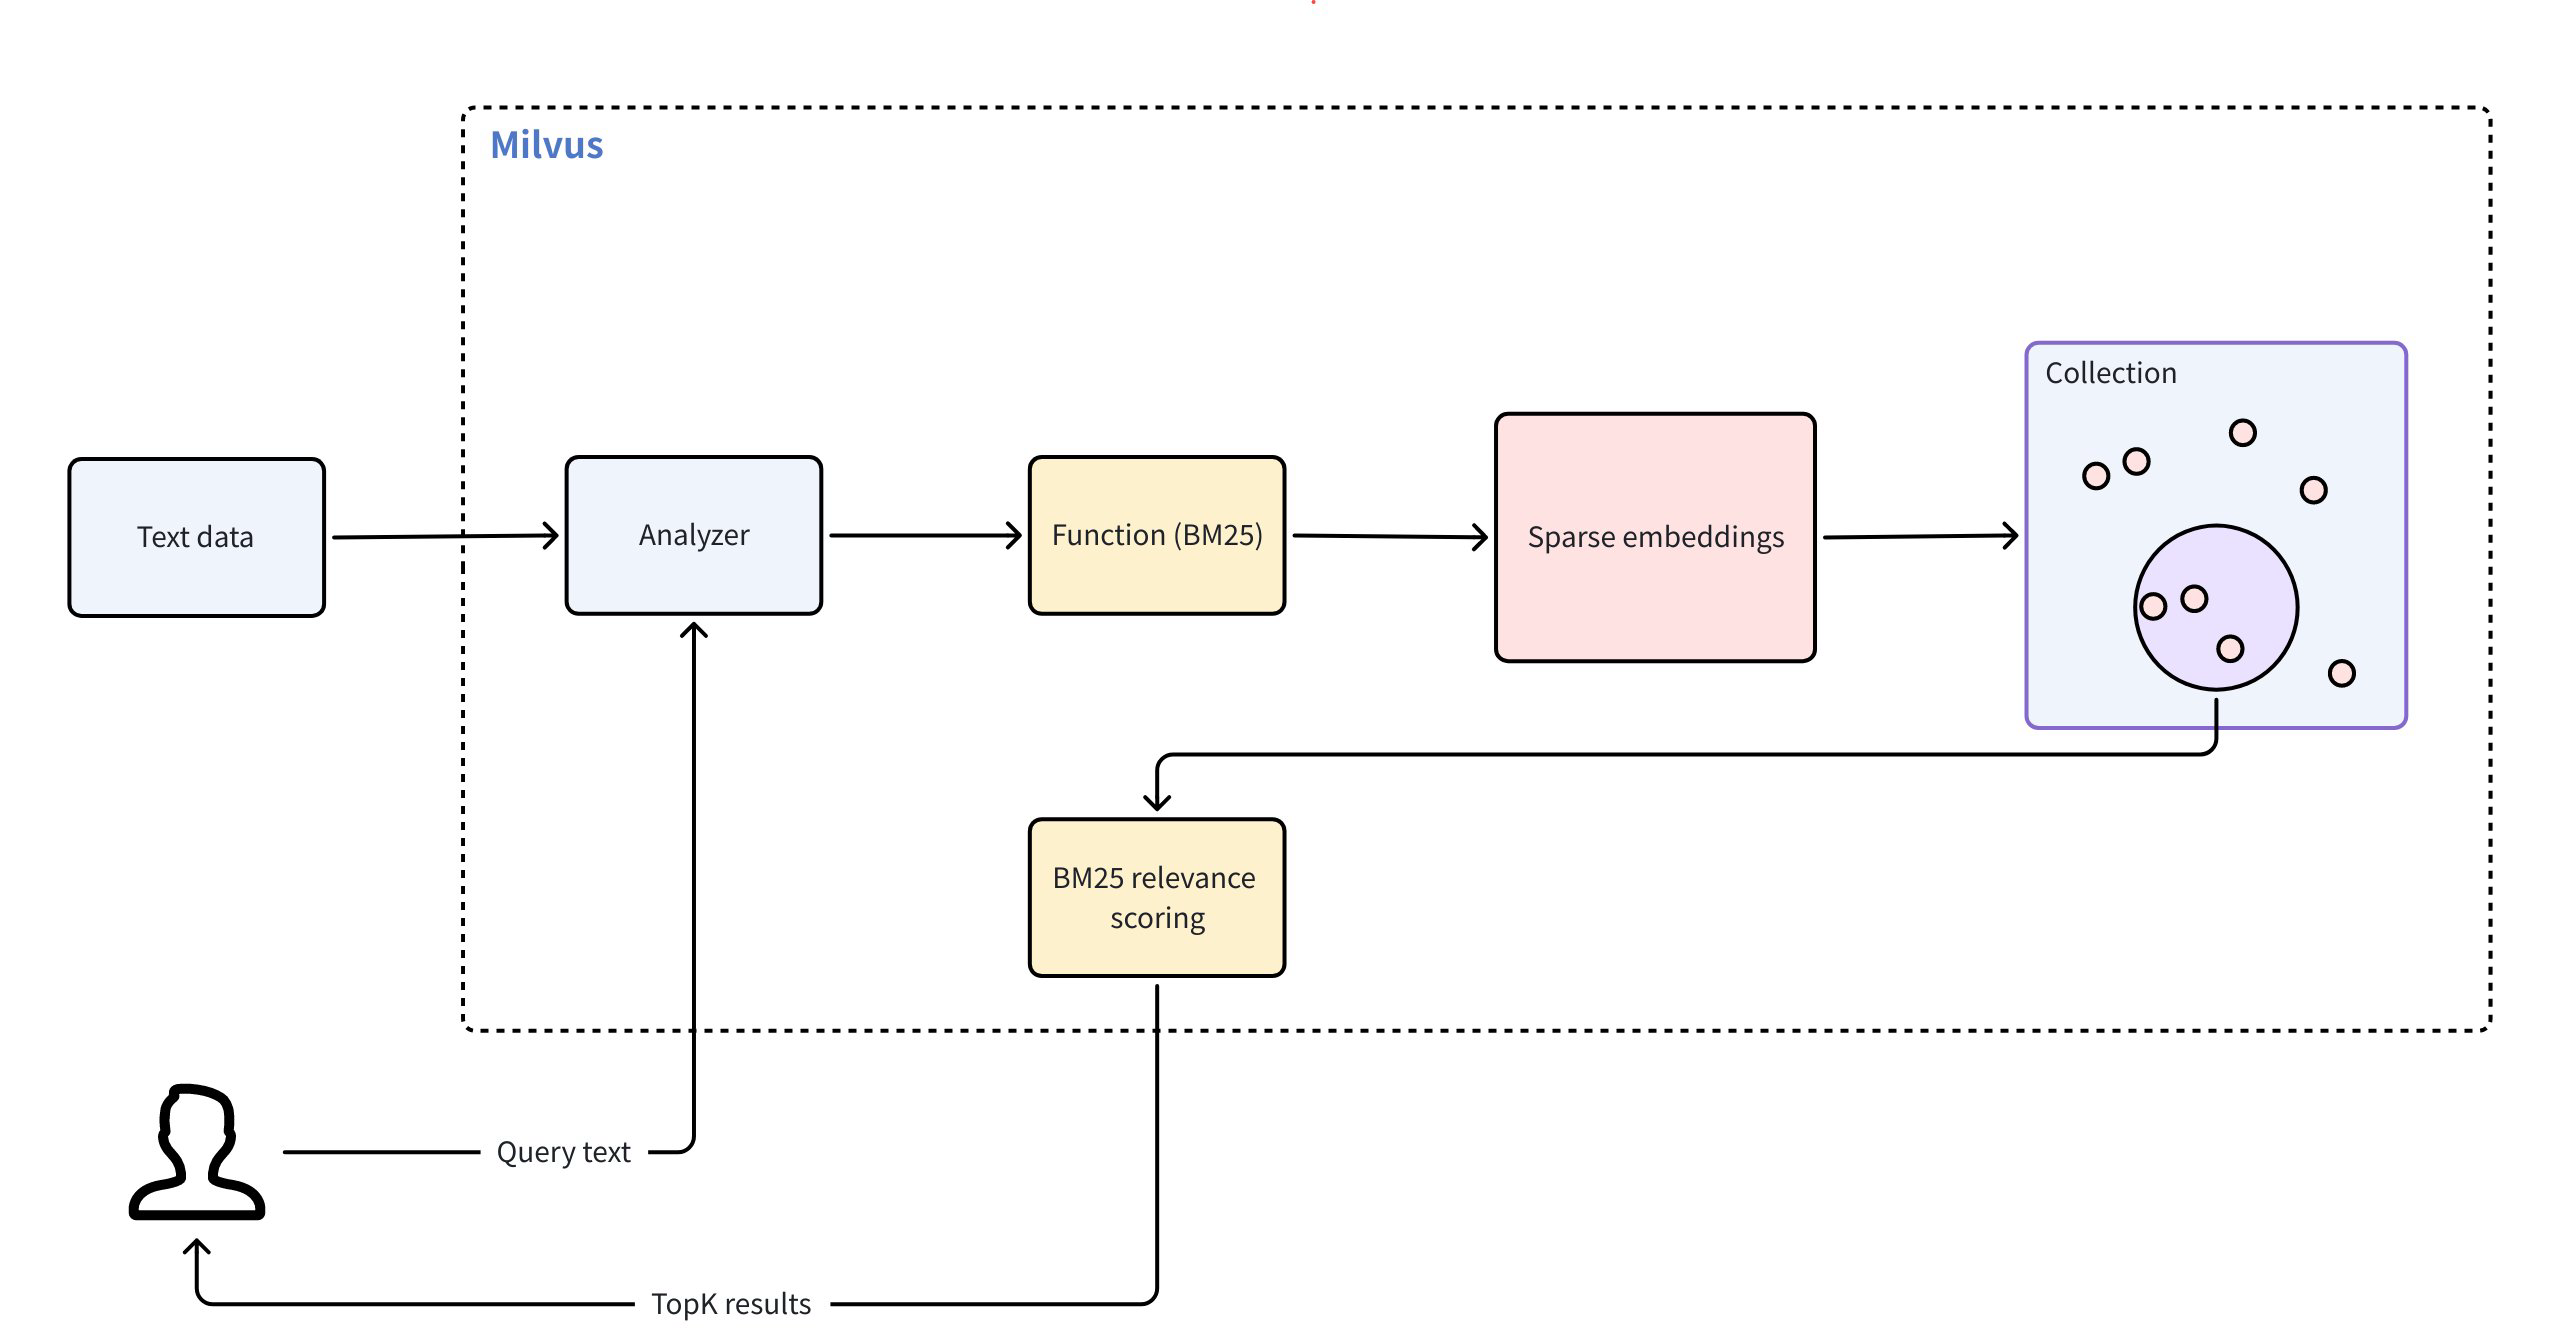
To use full text search, follow these main steps:
-
Create a collection: Set up the required fields and define a BM25 function that converts raw text into sparse embeddings.
-
Insert data: Ingest your raw text documents to the collection.
-
Perform searches: Use natural-language query text to retrieve ranked results based on BM25 relevance.
Create a collection for BM25 full text search
To enable BM25-powered full text search, you must prepare a collection with the required fields, define a BM25 function to generate sparse vectors, configure an index, and then create the collection.
Define schema fields
Your collection schema must include at least three required fields:
-
Primary field: Uniquely identifies each entity in the collection.
-
String field (
VARCHARorTEXT): Stores raw text documents. You must setenable_analyzer=Trueso that Zilliz Cloud can process the text for BM25 relevance ranking. By default, Zilliz Cloud uses thestandardanalyzer; to configure a different analyzer, refer to Analyzer Overview. The examples on this page useVARCHAR; for long text, define the field asTEXTand omitmax_length. For a complete example, refer to Text Field. -
Sparse vector field (
SPARSE_FLOAT_VECTOR): Stores sparse embeddings automatically generated by the BM25 function.
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
from pymilvus import MilvusClient, DataType, Function, FunctionType

client = MilvusClient(
    uri="YOUR_CLUSTER_ENDPOINT",
    token="YOUR_CLUSTER_TOKEN"
)

schema = client.create_schema()

schema.add_field(field_name="id", datatype=DataType.INT64, is_primary=True, auto_id=True) # Primary field
schema.add_field(field_name="text", datatype=DataType.VARCHAR, max_length=1000, enable_analyzer=True) # Text field
schema.add_field(field_name="sparse", datatype=DataType.SPARSE_FLOAT_VECTOR) # Sparse vector field; no dim required for sparse vectors
import io.milvus.v2.common.DataType;
import io.milvus.v2.service.collection.request.AddFieldReq;
import io.milvus.v2.service.collection.request.CreateCollectionReq;

CreateCollectionReq.CollectionSchema schema = CreateCollectionReq.CollectionSchema.builder()
        .build();
schema.addField(AddFieldReq.builder()
        .fieldName("id")
        .dataType(DataType.Int64)
        .isPrimaryKey(true)
        .autoID(true)
        .build());
schema.addField(AddFieldReq.builder()
        .fieldName("text")
        .dataType(DataType.VarChar)
        .maxLength(1000)
        .enableAnalyzer(true)
        .build());
schema.addField(AddFieldReq.builder()
        .fieldName("sparse")
        .dataType(DataType.SparseFloatVector)
        .build());
import (
    "context"
    "fmt"

    "github.com/milvus-io/milvus/client/v3/column"
    "github.com/milvus-io/milvus/client/v3/entity"
    "github.com/milvus-io/milvus/client/v3/index"
    "github.com/milvus-io/milvus/client/v3/milvusclient"
)

ctx, cancel := context.WithCancel(context.Background())
defer cancel()

milvusAddr := "YOUR_CLUSTER_ENDPOINT"
client, err := milvusclient.New(ctx, &milvusclient.ClientConfig{
    Address: milvusAddr,
})
if err != nil {
    fmt.Println(err.Error())
    // handle error
}
defer client.Close(ctx)

schema := entity.NewSchema()
schema.WithField(entity.NewField().
    WithName("id").
    WithDataType(entity.FieldTypeInt64).
    WithIsPrimaryKey(true).
    WithIsAutoID(true),
).WithField(entity.NewField().
    WithName("text").
    WithDataType(entity.FieldTypeVarChar).
    WithEnableAnalyzer(true).
    WithMaxLength(1000),
).WithField(entity.NewField().
    WithName("sparse").
    WithDataType(entity.FieldTypeSparseVector),
)
use milvus::v2::prelude::*;

let schema = CollectionSchema::new()
    .add_field(FieldSchema::new().name("id").data_type(DataType::Int64).primary_key(true).auto_id(true))
    .add_field(FieldSchema::new().name("text").data_type(DataType::VarChar).max_length(1000).enable_analyzer(true))
    .add_field(FieldSchema::new().name("sparse").data_type(DataType::SparseFloatVector));
#include "milvus/MilvusClientV2.h"

auto client = milvus::MilvusClientV2::Create();

milvus::ConnectParam connect_param{"YOUR_CLUSTER_ENDPOINT", "YOUR_CLUSTER_TOKEN"};
auto status = client->Connect(connect_param);
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

milvus::CollectionSchemaPtr schema = std::make_shared<milvus::CollectionSchema>();
schema->AddField({"id", milvus::DataType::INT64, "", true, true});
schema->AddField(milvus::FieldSchema("text", milvus::DataType::VARCHAR).WithMaxLength(1000).EnableAnalyzer(true));
schema->AddField(milvus::FieldSchema("sparse", milvus::DataType::SPARSE_FLOAT_VECTOR));
import { MilvusClient, DataType } from "@zilliz/milvus2-sdk-node";

const address = "YOUR_CLUSTER_ENDPOINT";
const token = "YOUR_CLUSTER_TOKEN";
const client = new MilvusClient({address, token});
const schema = [
  {
    name: "id",
    data_type: DataType.Int64,
    is_primary_key: true,
  },
  {
    name: "text",
    data_type: "VarChar",
    enable_analyzer: true,
    enable_match: true,
    max_length: 1000,
  },
  {
    name: "sparse",
    data_type: DataType.SparseFloatVector,
  },
];

console.log(schema);
export schema='{
        "autoId": true,
        "enabledDynamicField": false,
        "fields": [
            {
                "fieldName": "id",
                "dataType": "Int64",
                "isPrimary": true
            },
            {
                "fieldName": "text",
                "dataType": "VarChar",
                "elementTypeParams": {
                    "max_length": 1000,
                    "enable_analyzer": true
                }
            },
            {
                "fieldName": "sparse",
                "dataType": "SparseFloatVector"
            }
        ]
    }'
In the preceding config,
-
id: serves as the primary key and is automatically generated withauto_id=True. -
text: stores your raw text data for full text search operations. The field can useVARCHARfor bounded text orTEXTfor long source content. -
sparse: a vector field reserved to store internally generated sparse embeddings for full text search operations. The data type must beSPARSE_FLOAT_VECTOR.
Define the BM25 function
The BM25 function converts tokenized text into sparse vectors that support BM25 scoring.
Define the function and add it to your schema:
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
bm25_function = Function(
    name="text_bm25_emb", # Function name
    input_field_names=["text"], # Name of the VARCHAR or TEXT field containing raw text data
    output_field_names=["sparse"], # Name of the SPARSE_FLOAT_VECTOR field reserved to store generated embeddings
    function_type=FunctionType.BM25, # Set to `BM25`
)

schema.add_function(bm25_function)
import io.milvus.common.clientenum.FunctionType;
import io.milvus.v2.service.collection.request.CreateCollectionReq.Function;

import java.util.*;

schema.addFunction(Function.builder()
        .functionType(FunctionType.BM25)
        .name("text_bm25_emb")
        .inputFieldNames(Collections.singletonList("text"))
        .outputFieldNames(Collections.singletonList("sparse"))
        .build());
function := entity.NewFunction().
    WithName("text_bm25_emb").
    WithInputFields("text").
    WithOutputFields("sparse").
    WithType(entity.FunctionTypeBM25)
schema.WithFunction(function)
use milvus::v2::prelude::*;

let bm25_function = Function::new()
    .name("text_bm25_emb")
    .function_type(FunctionType::Bm25)
    .input_fields(["text"])
    .output_fields(["sparse"]);

let schema = schema.add_function(bm25_function);
milvus::FunctionPtr function = std::make_shared<milvus::Function>("text_bm25_emb", milvus::FunctionType::BM25);
function->AddInputFieldName("text");
function->AddOutputFieldName("sparse");
schema->AddFunction(function);
const functions = [
    {
      name: 'text_bm25_emb',
      description: 'bm25 function',
      type: FunctionType.BM25,
      input_field_names: ['text'],
      output_field_names: ['sparse'],
      params: {},
    },
];
export schema='{
        "autoId": true,
        "enabledDynamicField": false,
        "fields": [
            {
                "fieldName": "id",
                "dataType": "Int64",
                "isPrimary": true
            },
            {
                "fieldName": "text",
                "dataType": "VarChar",
                "elementTypeParams": {
                    "max_length": 1000,
                    "enable_analyzer": true
                }
            },
            {
                "fieldName": "sparse",
                "dataType": "SparseFloatVector"
            }
        ],
        "functions": [
            {
                "name": "text_bm25_emb",
                "type": "BM25",
                "inputFieldNames": ["text"],
                "outputFieldNames": ["sparse"],
                "params": {}
            }
        ]
    }'
Parameter | Description |
|---|---|
| The name of the function. This function converts your raw text from the |
| The name of the |
| The name of the field where the internally generated sparse vectors will be stored. For |
| The type of the function to use. Must be |
If multiple text fields require BM25 processing, define one BM25 function per field, each with a unique name and output field.
Configure the index
After defining the schema with necessary fields and the built-in function, set up the index for your collection. To simplify this process, use AUTOINDEX as the index_type, an option that allows Zilliz Cloud to choose and configure the most suitable index type based on the structure of your data.
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
index_params = client.prepare_index_params()

index_params.add_index(
    field_name="sparse",

    index_type="SPARSE_INVERTED_INDEX",
    metric_type="BM25",
    params={
        "inverted_index_algo": "DAAT_MAXSCORE",
        "bm25_k1": 1.2,
        "bm25_b": 0.75
    }

)
import io.milvus.v2.common.IndexParam;

Map<String,Object> params = new HashMap<>();
params.put("inverted_index_algo", "DAAT_MAXSCORE");
params.put("bm25_k1", 1.2);
params.put("bm25_b", 0.75);

List<IndexParam> indexes = new ArrayList<>();
indexes.add(IndexParam.builder()
        .fieldName("sparse")
        .indexType(IndexParam.IndexType.SPARSE_INVERTED_INDEX)
        .metricType(IndexParam.MetricType.BM25)
        .extraParams(params)
        .build());
indexOption := milvusclient.NewCreateIndexOption("my_collection", "sparse",
    index.NewSparseInvertedIndex(entity.BM25, 0.05))
indexOption.WithExtraParam("inverted_index_algo", "DAAT_MAXSCORE")
indexOption.WithExtraParam("bm25_k1", 1.2)
indexOption.WithExtraParam("bm25_b", 0.75)
use std::collections::HashMap;

let index_params = IndexParam::new()
    .field_name("sparse")
    .index_type(IndexType::SparseInvertedIndex)
    .metric_type(MetricType::Bm25)
    .extra_params(HashMap::from([
        ("inverted_index_algo".into(), "DAAT_MAXSCORE".into()),
        ("bm25_k1".into(), "1.2".into()),
        ("bm25_b".into(), "0.75".into()),
    ]));
auto index_params = milvus::IndexDesc("sparse", "", milvus::IndexType::SPARSE_INVERTED_INDEX, milvus::MetricType::BM25);
index_params.AddExtraParam("inverted_index_algo", "DAAT_MAXSCORE");
index_params.AddExtraParam("bm25_k1", "1.2");
index_params.AddExtraParam("bm25_b", "0.75");
const index_params = [
  {
    field_name: "sparse",
    metric_type: "BM25",
    index_type: "SPARSE_INVERTED_INDEX",
    params: {
        "inverted_index_algo": "DAAT_MAXSCORE",
        "bm25_k1": 1.2,
        "bm25_b": 0.75
    }
  },
];
export indexParams='[
        {
            "fieldName": "sparse",
            "metricType": "BM25",
            "indexType": "SPARSE_INVERTED_INDEX",
            "params":{
               "inverted_index_algo": "DAAT_MAXSCORE",
               "bm25_k1": 1.2,
               "bm25_b": 0.75
            }
        }
    ]'
Parameter | Description |
|---|---|
| The name of the vector field to index. For full text search, this should be the field that stores the generated sparse vectors. In this example, set the value to |
| The type of the index to create. |
| The value for this parameter must be set to |
| A dictionary of additional parameters specific to the index. |
| The algorithm used for building and querying the index. Valid values:
|
| Controls the term frequency saturation. Higher values increase the importance of term frequencies in document ranking. Value range: [1.2, 2.0]. |
| Controls the extent to which document length is normalized. Values between 0 and 1 are typically used, with a default value of 0.75. A value of 0 means no length normalization, while a value of 1 means full length normalization. |
Create the collection
Now create the collection using the schema and index parameters defined.
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
client.create_collection(
    collection_name='my_collection',
    schema=schema,
    index_params=index_params
)

client.load_collection('my_collection')
import io.milvus.v2.service.collection.request.CreateCollectionReq;
import io.milvus.v2.service.collection.request.LoadCollectionReq;

CreateCollectionReq requestCreate = CreateCollectionReq.builder()
        .collectionName("my_collection")
        .collectionSchema(schema)
        .indexParams(indexes)
        .build();
client.createCollection(requestCreate);
client.loadCollection(LoadCollectionReq.builder()
        .collectionName("my_collection")
        .build());
err = client.CreateCollection(ctx,
    milvusclient.NewCreateCollectionOption("my_collection", schema).
        WithIndexOptions(indexOption))
if err != nil {
    fmt.Println(err.Error())
    // handle error
}

_, err = client.LoadCollection(ctx, milvusclient.NewLoadCollectionOption("my_collection"))
if err != nil {
    fmt.Println(err.Error())
    // handle error
}
use milvus::v2::prelude::*;

client.create_collection(
    CreateCollectionRequest::builder()
        .collection_name("my_collection")
        .schema(schema)
        .index_param(index_params)
        .build()?,
)
.await?;

client.load_collection(LoadCollectionRequest::builder().collection_name("my_collection").build()?).await?;
auto status = client->CreateCollection(milvus::CreateCollectionRequest()
                                    .WithCollectionName("my_collection")
                                    .WithCollectionSchema(schema)
                                    .AddIndex(std::move(index_params)));
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
await client.createCollection({
    collection_name: 'my_collection',
    schema: schema,
    index_params: index_params,
    functions: functions,
});

await client.loadCollection({ collection_name: 'my_collection' });
export CLUSTER_ENDPOINT="YOUR_CLUSTER_ENDPOINT"
export TOKEN="YOUR_CLUSTER_TOKEN"

curl --request POST \
--url "${CLUSTER_ENDPOINT}/v2/vectordb/collections/create" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
--header "Request-Timeout: 10" \
-d "{
    \"collectionName\": \"my_collection\",
    \"schema\": $schema,
    \"indexParams\": $indexParams
}"

curl --request POST \
--url "${CLUSTER_ENDPOINT}/v2/vectordb/collections/load" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
--data '{
    "collectionName": "my_collection"
}'
Insert text data
After setting up your collection and index, you can insert text data. You only need to provide the raw text — the BM25 function defined earlier automatically generates the corresponding sparse vector for each text entry.
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
client.insert('my_collection', [
    {'text': 'information retrieval is a field of study.'},
    {'text': 'information retrieval focuses on finding relevant information in large datasets.'},
    {'text': 'data mining and information retrieval overlap in research.'},
])
import com.google.gson.Gson;
import com.google.gson.JsonObject;

import io.milvus.v2.service.vector.request.InsertReq;

Gson gson = new Gson();
List<JsonObject> rows = Arrays.asList(
        gson.fromJson("{\"text\": \"information retrieval is a field of study.\"}", JsonObject.class),
        gson.fromJson("{\"text\": \"information retrieval focuses on finding relevant information in large datasets.\"}", JsonObject.class),
        gson.fromJson("{\"text\": \"data mining and information retrieval overlap in research.\"}", JsonObject.class)
);

client.insert(InsertReq.builder()
        .collectionName("my_collection")
        .data(rows)
        .build());
_, err = client.Insert(ctx, milvusclient.NewColumnBasedInsertOption("my_collection").
    WithVarcharColumn("text", []string{
        "information retrieval is a field of study.",
        "information retrieval focuses on finding relevant information in large datasets.",
        "data mining and information retrieval overlap in research.",
    }),
)
if err != nil {
    fmt.Println(err.Error())
    // handle error
}
use milvus::v2::prelude::*;
use serde_json::json;

client.insert(
    InsertRequest::builder()
        .collection_name("my_collection")
        .rows(vec![
            json!({"text": "information retrieval is a field of study."}),
            json!({"text": "information retrieval focuses on finding relevant information in large datasets."}),
            json!({"text": "data mining and information retrieval overlap in research."}),
        ])
        .build()?,
)
.await?;
milvus::EntityRows data = {
    {{"text", "information retrieval is a field of study."}},
    {{"text", "information retrieval focuses on finding relevant information in large datasets."}},
    {{"text", "data mining and information retrieval overlap in research."}}
};

milvus::InsertResponse response;
auto status = client->Insert(milvus::InsertRequest()
                                .WithCollectionName("my_collection")
                                .WithRowsData(std::move(data))
                                , response);
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
await client.insert({
    collection_name: 'my_collection',
    data: [
        {'text': 'information retrieval is a field of study.'},
        {'text': 'information retrieval focuses on finding relevant information in large datasets.'},
        {'text': 'data mining and information retrieval overlap in research.'},
    ],
});
curl --request POST \
--url "${CLUSTER_ENDPOINT}/v2/vectordb/entities/insert" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
--header "Request-Timeout: 10" \
-d '{
    "data": [
        {"text": "information retrieval is a field of study."},
        {"text": "information retrieval focuses on finding relevant information in large datasets."},
        {"text": "data mining and information retrieval overlap in research."}
    ],
    "collectionName": "my_collection"
}'
Perform full text search
Once you've inserted data into your collection, you can search it with raw text queries. Zilliz Cloud automatically converts your query into a sparse vector, ranks the matched results using the BM25 algorithm, and returns the top limit results.
You can highlight the matched terms in search results by configuring a text highlighter. See Text Highlighter for details.
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
res = client.search(
    collection_name='my_collection',
    data=['whats the focus of information retrieval?'],
    anns_field='sparse',
    output_fields=['text'], # Fields to return in search results; sparse field cannot be output
    limit=3,
    search_params={"metric_type": "BM25", "params": {"level": 10}},
)

print(res)
import io.milvus.v2.service.vector.request.SearchReq;
import io.milvus.v2.service.vector.request.data.EmbeddedText;
import io.milvus.v2.service.vector.response.SearchResp;

Map<String,Object> searchParams = new HashMap<>();
searchParams.put("metric_type", "BM25");
searchParams.put("level", 10);

SearchResp searchResp = client.search(SearchReq.builder()
        .collectionName("my_collection")
        .data(Collections.singletonList(new EmbeddedText("whats the focus of information retrieval?")))
        .annsField("sparse")
        .topK(3)
        .searchParams(searchParams)
        .outputFields(Collections.singletonList("text"))
        .build());
annSearchParams := index.NewCustomAnnParam()
annSearchParams.WithExtraParam("metric_type", "BM25")
resultSets, err := client.Search(ctx, milvusclient.NewSearchOption(
    "my_collection", // collectionName
    3,               // limit
    []entity.Vector{entity.Text("whats the focus of information retrieval?")},
).WithConsistencyLevel(entity.ClStrong).
    WithANNSField("sparse").
    WithAnnParam(annSearchParams).
    WithOutputFields("text"))
if err != nil {
    fmt.Println(err.Error())
    // handle error
}

for _, resultSet := range resultSets {
    fmt.Println("IDs: ", resultSet.IDs.FieldData().GetScalars())
    fmt.Println("Scores: ", resultSet.Scores)
    fmt.Println("text: ", resultSet.GetColumn("text").FieldData().GetScalars())
}
use milvus::v2::prelude::*;

let res = client.search(
    SearchRequest::builder()
        .collection_name("my_collection")
        .vector_field("sparse")
        .vectors(SearchVectors::EmbeddedText(vec!["whats the focus of information retrieval?".to_string()]))
        .metric_type(MetricType::Bm25)
        .limit(3)
        .output_fields(["text"])
        .build()?,
)
.await?;

println!("{:?}", res.results());
auto request = milvus::SearchRequest()
                       .WithCollectionName("my_collection")
                       .AddEmbeddedText("whats the focus of information retrieval?")
                       .WithLimit(3)
                       .WithAnnsField("sparse")
                       .AddExtraParam("metric_type", "BM25")
                       .AddOutputField("text");

milvus::SearchResponse response;
auto status = client->Search(request, response);
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
await client.search({
    collection_name: 'my_collection',
    data: ['whats the focus of information retrieval?'],
    anns_field: 'sparse',
    output_fields: ['text'],
    params: { metric_type: 'BM25' },
    limit: 3,
});
curl --request POST \
--url "${CLUSTER_ENDPOINT}/v2/vectordb/entities/search" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
--header "Request-Timeout: 10" \
--data-raw '{
    "collectionName": "my_collection",
    "data": [
        "whats the focus of information retrieval?"
    ],
    "annsField": "sparse",
    "limit": 3,
    "outputFields": [
        "text"
    ],
    "searchParams":{
        "metric_type": "BM25",
        "params":{}
    }
}'
| Parameter | Description |
|---|---|
search_params | A dictionary containing search parameters. |
params.level | Controls the search precision with simplified search optimization. For details, refer to Tune Recall Rate. |
data | Raw query text in natural language. Zilliz Cloud automatically converts your text query into sparse vectors using the BM25 function - do not provide pre-computed vectors. |
anns_field | The name of the field that contains internally generated sparse vectors. |
output_fields | List of field names to return in search results. Supports all fields except the sparse vector field containing BM25-generated embeddings. Common output fields include the primary key field (e.g., id) and the original text field (e.g., text). For more information, refer to FAQ. |
limit | Maximum number of top matches to return. |
FAQ
Can I output or access the sparse vectors generated by the BM25 function in full text search?
No, the sparse vectors generated by the BM25 function are not directly accessible or returnable in full text search. Here are the details:
-
The BM25 function generates sparse vectors internally for ranking and retrieval.
-
These vectors are stored in the sparse field but cannot be included in
output_fields. -
You can only output the original text fields and metadata (like
id,text).
Example:
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
search_params = {"metric_type": "BM25"}

# ❌ This throws an error - you cannot output the sparse field
client.search(
    collection_name='my_collection',
    data=['query text'],
    anns_field='sparse',
    output_fields=['text', 'sparse'],  # 'sparse' causes an error
    limit=3,
    search_params=search_params
)

# ✅ This works - output text fields only
client.search(
    collection_name='my_collection',
    data=['query text'],
    anns_field='sparse',
    output_fields=['text'],
    limit=3,
    search_params=search_params
)
// Searching with the sparse field in outputFields throws an error.
// Only output the original text and metadata fields.
SearchResp searchResp = client.search(SearchReq.builder()
        .collectionName("my_collection")
        .data(Collections.singletonList(new EmbeddedText("query text")))
        .annsField("sparse")
        .topK(3)
        .outputFields(Collections.singletonList("text"))
        .build());
// Searching with the sparse field in output_fields throws an error.
// Only output the original text and metadata fields.
resultSets, err := client.Search(ctx, milvusclient.NewSearchOption(
    "my_collection",
    3,
    []entity.Vector{entity.Text("query text")},
).WithConsistencyLevel(entity.ClStrong).
    WithANNSField("sparse").
    WithAnnParam(index.NewCustomAnnParam()).
    WithOutputFields("text"))
use milvus::v2::prelude::*;

// Searching with the sparse field in output_fields throws an error.
// Only output the original text and metadata fields.
let request = SearchRequest::builder()
    .collection_name("my_collection")
    .vector_field("sparse")
    .vectors(SearchVectors::EmbeddedText(vec!["query text".to_string()]))
    .limit(3)
    .output_fields(["text"])
    .build()?;
// Searching with the sparse field in output_fields throws an error.
// Only output the original text and metadata fields.
milvus::SearchRequest request = milvus::SearchRequest()
    .WithCollectionName("my_collection")
    .AddEmbeddedText("query text")
    .WithLimit(3)
    .WithAnnsField("sparse")
    .AddOutputField("text");
// Searching with the sparse field in output_fields throws an error.
// Only output the original text and metadata fields.
await client.search({
    collection_name: 'my_collection',
    data: ['query text'],
    anns_field: 'sparse',
    output_fields: ['text'],
    limit: 3,
});
curl --request POST \
--url "${CLUSTER_ENDPOINT}/v2/vectordb/entities/search" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
--header "Request-Timeout: 10" \
--data-raw '{
    "collectionName": "my_collection",
    "data": ["query text"],
    "annsField": "sparse",
    "limit": 3,
    "outputFields": ["text"]
}'
Why do I need to define a sparse vector field if I can't access it?
The sparse vector field serves as an internal search index, similar to database indexes that users don't directly interact with.
Design rationale:
-
Separation of concerns: You work with text for input and output, and Zilliz Cloud handles the vectors internally.
-
Performance: Pre-computed sparse vectors enable fast BM25 ranking during queries.
-
User experience: Complex vector operations are abstracted away behind a simple text interface.
If you need vector access:
-
Use manual sparse vector operations instead of full text search.
-
Create separate collections for custom sparse vector workflows.
For details, refer to Sparse Vector.