MinHash Function
Private PreviewThe MinHash function converts raw text into binary vectors that approximate Jaccard similarity between documents. It applies text shingling and multiple hash functions to produce fixed-length signature vectors, enabling fast near-duplicate detection and document deduplication at scale.
As a built-in function, MinHash runs within Zilliz Cloud and does not require external model inference or preprocessing. You insert raw text, and Zilliz Cloud generates the MinHash signature vectors automatically.
Limits
-
The output field must be a
BINARY_VECTORwith a dimension that satisfiesdim % 32 == 0, because each MinHash signature is a 32-bit hash value. -
The
dimof the binary vector field must equal32 * num_hashes. A mismatch causes an error. -
When using
MINHASH_LSHindex with MinHash function output,mh_element_bit_widthmust be set to32.
How MinHash works
Expand to see how it works
MinHash is a locality-sensitive hashing technique that estimates Jaccard similarity between sets. In Zilliz Cloud, the MinHash function follows this pipeline: you provide raw text as input, and Zilliz Cloud produces a binary vector as output — handling all intermediate steps internally.
The overall workflow consists of a shared text processing pipeline used by both document ingestion and query processing, followed by phase-specific operations for storage and retrieval.
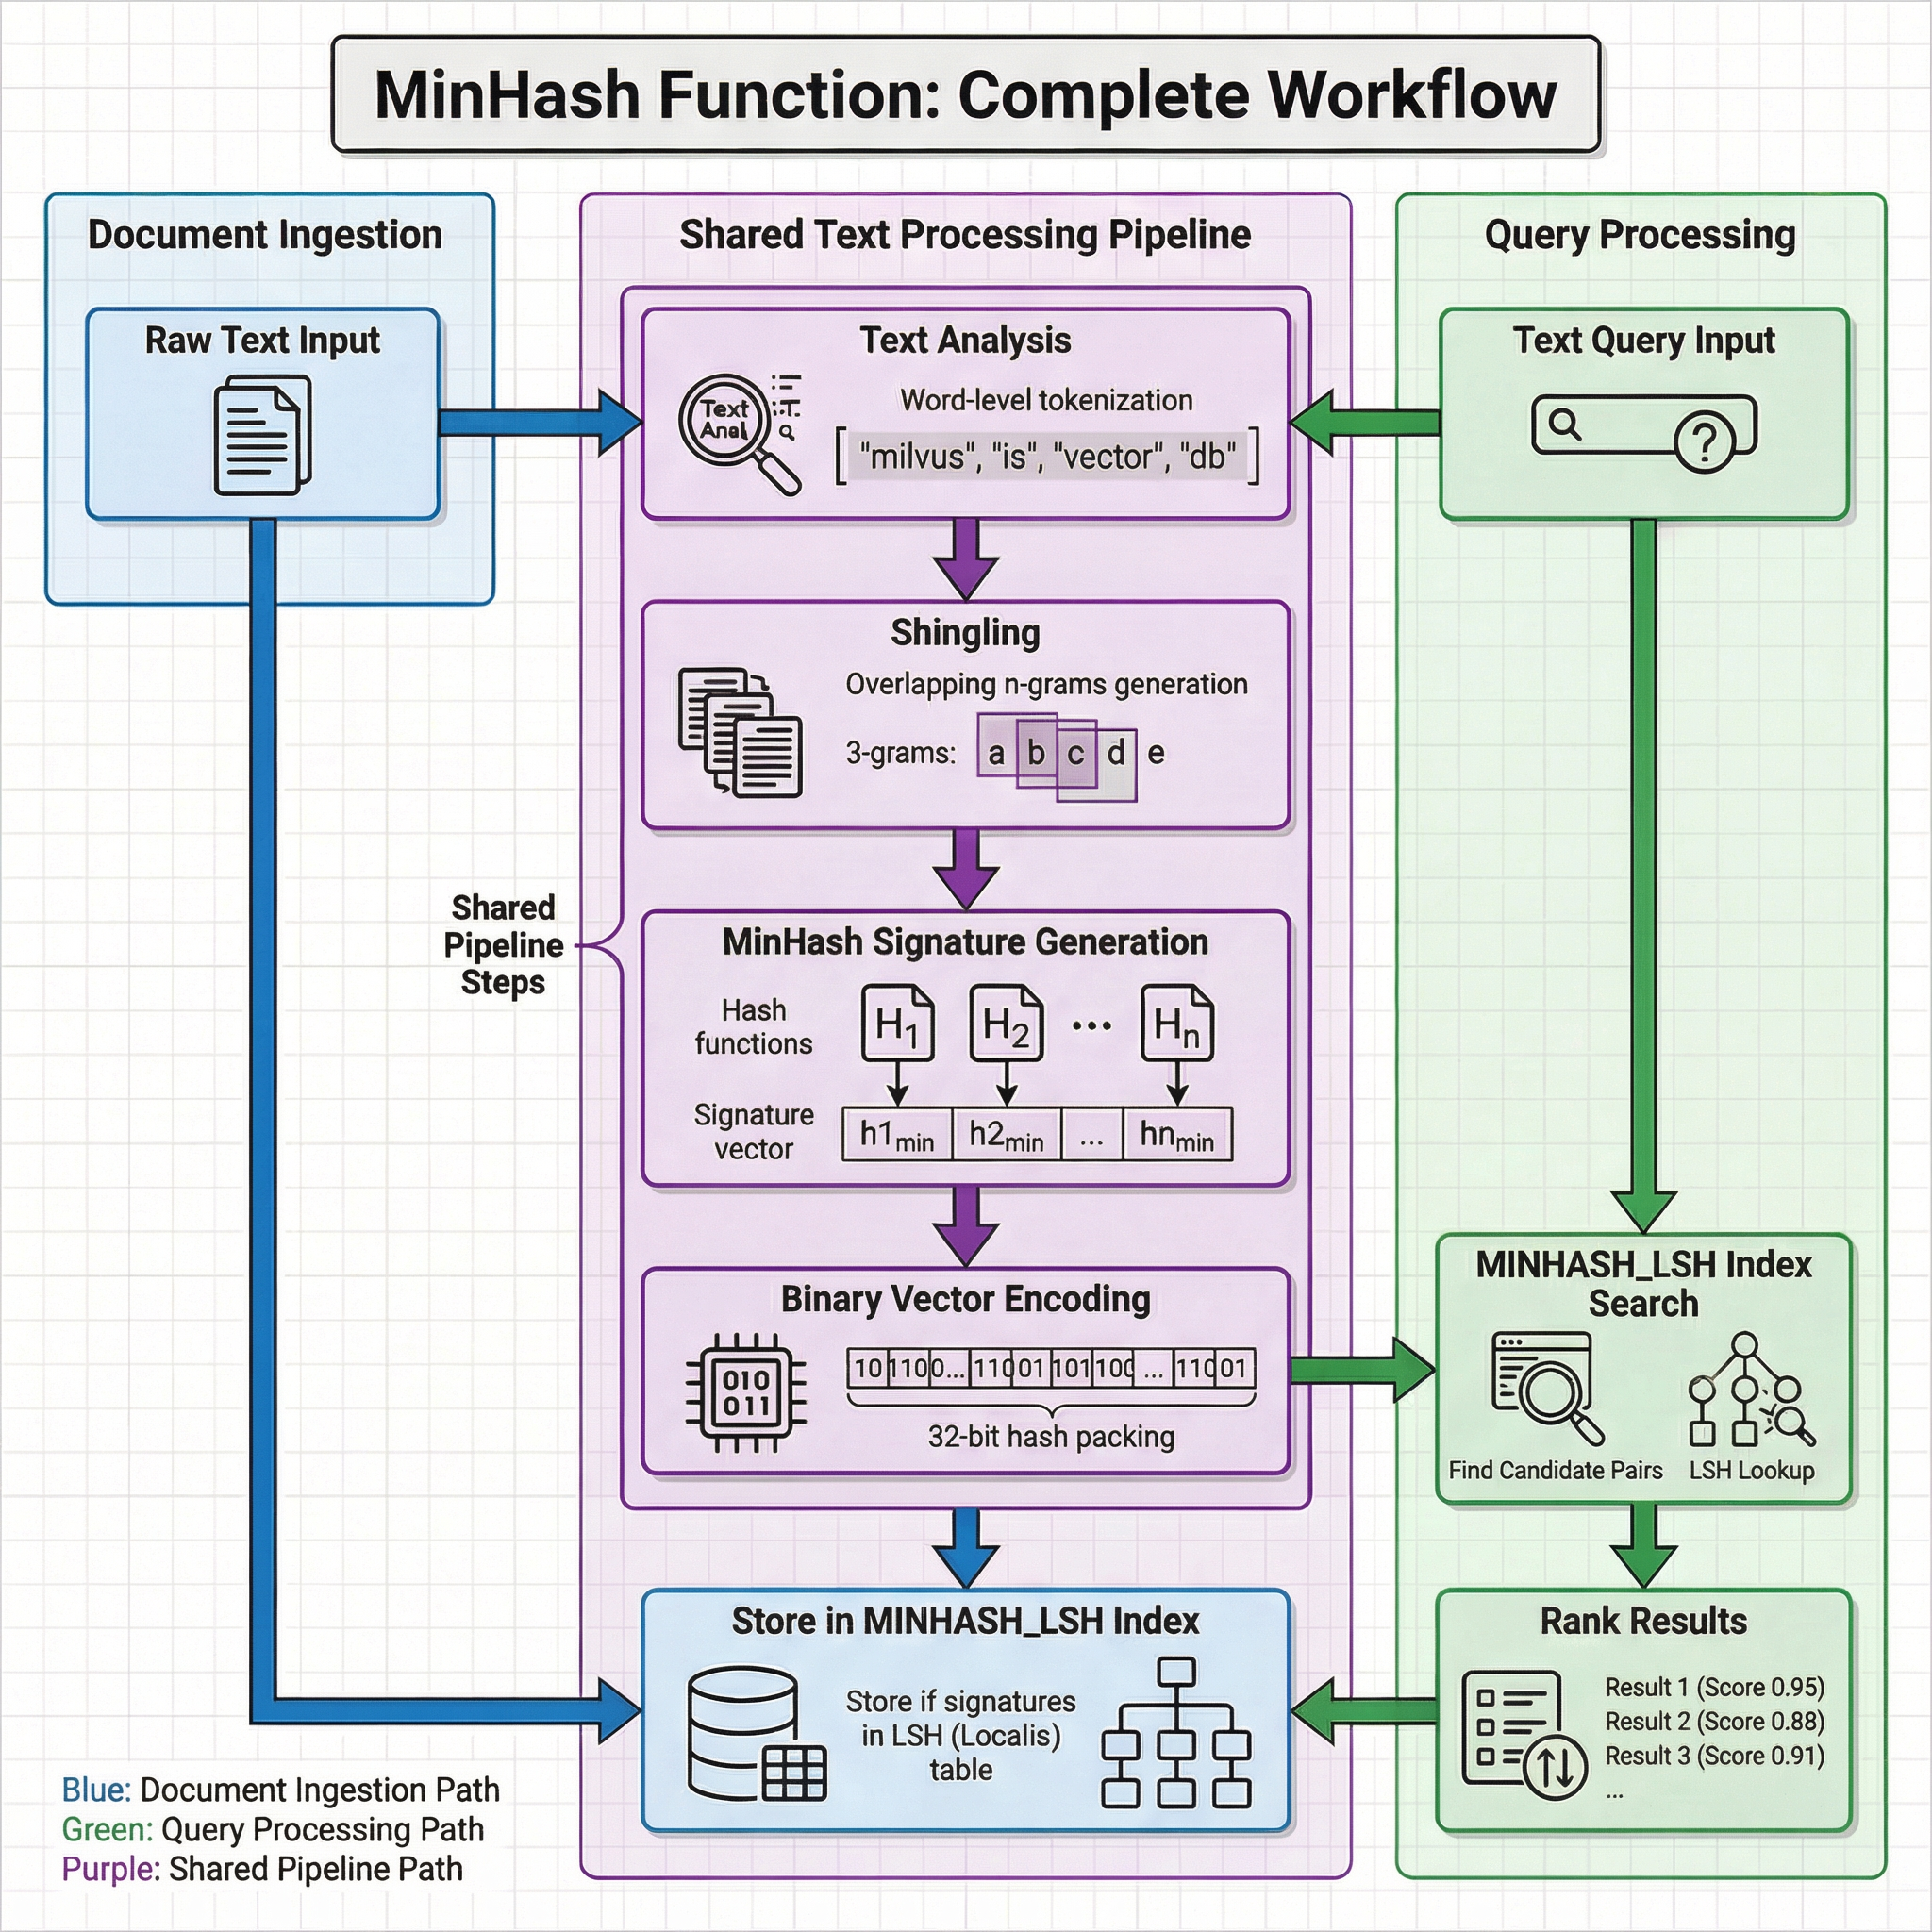
Shared text processing pipeline
Both document ingestion and query processing pass raw text through the same four-stage transformation:
-
Text analysis: The text is processed by an analyzer (when
token_levelis"word") or used directly (whentoken_levelis"char"). Word-level tokenization applies the analyzer configured on the input field to segment text into terms — for example,"milvus is vector db"becomes["milvus", "is", "vector", "db"]. -
Shingling: The tokens are split into overlapping n-grams (shingles) of size
shingle_size. For example, with 3-grams at word level, the tokens["information", "retrieval", "is", "a", "field"]become shingles like["information retrieval is", "retrieval is a", "is a field"]. -
MinHash signature generation: Multiple hash functions (H1, H2, ..., Hn, where n =
num_hashes) are applied to the shingle set. For each hash function, the minimum hash value across all shingles is selected. The collection of these minimum values forms the MinHash signature — a fixed-length representation that approximates the Jaccard similarity of the original document. -
Binary vector encoding: Each signature value is a 32-bit hash, and the full signature is packed into a
BINARY_VECTORof dimension32 * num_hashes.
Document ingestion
During insertion, the binary vector produced by the shared pipeline is stored in the MINHASH_LSH index. The index maintains an LSH (Locality-Sensitive Hashing) table that groups similar signatures into the same buckets, enabling fast candidate retrieval at query time.
Query processing
During search, the query text goes through the same shared pipeline to produce a binary vector. This vector is used to perform an LSH lookup in the MINHASH_LSH index, which quickly identifies candidate pairs that are likely similar. Without Jaccard refinement, Zilliz Cloud returns LSH candidates that are not ranked by estimated Jaccard similarity. When Jaccard refinement is enabled, Zilliz Cloud uses the stored raw MinHash signatures to rank the candidates by estimated Jaccard similarity and return the top-K results.
Because both paths share the same transformation logic, two documents with highly overlapping content produce similar MinHash signatures. This makes the function effective for finding near-duplicates even when documents differ in word order, formatting, or minor phrasing.
Before you start
Before using the MinHash function, plan your collection schema to include the following:
-
A text field for raw content
Your collection must include a
VARCHARfield to store raw text. This field serves as the input to the MinHash function. -
An analyzer for the text field (when using word-level tokenization)
If
token_levelis set to"word"(default), the text field must have an analyzer enabled. The analyzer defines how text is tokenized before shingling. By default, Zilliz Cloud uses thestandardanalyzer. To configure a different analyzer, refer to Choose the Right Analyzer for Your Use Case. -
A binary vector field for MinHash output
Your collection must include a
BINARY_VECTORfield to store the binary vectors generated by the MinHash function. The dimension must equal32 * num_hashes.
Step 1: Create a collection with a MinHash function
To use the MinHash function, define it when creating the collection. The function becomes part of the collection schema and is applied automatically during data insertion and search.
Define schema fields
Your collection schema must include at least three fields:
-
Primary field: Uniquely identifies each entity in the collection.
-
Text field (
VARCHAR): Stores raw text documents. Setenable_analyzer=Trueso Zilliz Cloud can process the text for MinHash signature generation. By default, Zilliz Cloud uses thestandardanalyzer for text analysis. To configure a different analyzer, refer to Choose the Right Analyzer for Your Use Case. -
Binary vector field (
BINARY_VECTOR): Stores binary vectors automatically generated by the MinHash function. The dimension must equal32 * num_hashes.
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
from pymilvus import MilvusClient, DataType, Function, FunctionType

client = MilvusClient(uri="YOUR_CLUSTER_ENDPOINT", token="YOUR_CLUSTER_TOKEN")

schema = client.create_schema()

schema.add_field(field_name="id", datatype=DataType.INT64, is_primary=True, auto_id=True)
schema.add_field(field_name="document_content", datatype=DataType.VARCHAR, max_length=9000, enable_analyzer=True)
schema.add_field(field_name="binary_vector", datatype=DataType.BINARY_VECTOR, dim=8192)
import io.milvus.v2.client.ConnectConfig;
import io.milvus.v2.client.MilvusClientV2;
import io.milvus.v2.common.DataType;
import io.milvus.v2.service.collection.request.AddFieldReq;
import io.milvus.v2.service.collection.request.CreateCollectionReq;

MilvusClientV2 client = new MilvusClientV2(ConnectConfig.builder()
        .uri("YOUR_CLUSTER_ENDPOINT")
        .token("YOUR_CLUSTER_TOKEN")
        .build());

CreateCollectionReq.CollectionSchema schema = CreateCollectionReq.CollectionSchema.builder().build();
schema.addField(AddFieldReq.builder()
        .fieldName("id")
        .dataType(DataType.Int64)
        .isPrimaryKey(true)
        .autoID(true)
        .build());
schema.addField(AddFieldReq.builder()
        .fieldName("document_content")
        .dataType(DataType.VarChar)
        .maxLength(9000)
        .enableAnalyzer(true)
        .build());
schema.addField(AddFieldReq.builder()
        .fieldName("binary_vector")
        .dataType(DataType.BinaryVector)
        .dimension(8192)
        .build());
import (
    "context"
    "log"

    "github.com/milvus-io/milvus/client/v3/entity"
    "github.com/milvus-io/milvus/client/v3/milvusclient"
)

ctx := context.Background()
client, err := milvusclient.New(ctx, &milvusclient.ClientConfig{
    Address: "YOUR_CLUSTER_ENDPOINT",
    APIKey:  "YOUR_CLUSTER_TOKEN",
})
if err != nil {
    log.Fatal(err)
}

schema := entity.NewSchema().
    WithField(entity.NewField().WithName("id").WithDataType(entity.FieldTypeInt64).WithIsPrimaryKey(true).WithIsAutoID(true)).
    WithField(entity.NewField().WithName("document_content").WithDataType(entity.FieldTypeVarChar).WithMaxLength(9000).WithEnableAnalyzer(true)).
    WithField(entity.NewField().WithName("binary_vector").WithDataType(entity.FieldTypeBinaryVector).WithDim(8192))
use milvus::v2::prelude::*;

let config = ConnectConfig::new().uri("YOUR_CLUSTER_ENDPOINT");
let client = ClientV2::new(&config).await?;

let schema = CollectionSchema::new()
    .add_field(FieldSchema::new().name("id").data_type(DataType::Int64).primary_key(true).auto_id(true))
    .add_field(FieldSchema::new().name("document_content").data_type(DataType::VarChar).max_length(9000).enable_analyzer(true))
    .add_field(FieldSchema::new().name("binary_vector").data_type(DataType::BinaryVector).dimension(8192));
#include "milvus/MilvusClientV2.h"
#include <iostream>

auto client = milvus::MilvusClientV2::Create();
milvus::ConnectParam connect_param{"YOUR_CLUSTER_ENDPOINT"};
auto status = client->Connect(connect_param);
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

auto schema = std::make_shared<milvus::CollectionSchema>();
schema->AddField(milvus::FieldSchema("id", milvus::DataType::INT64).WithPrimaryKey(true).WithAutoID(true));
schema->AddField(milvus::FieldSchema("document_content", milvus::DataType::VARCHAR).WithMaxLength(9000).EnableAnalyzer(true));
schema->AddField(milvus::FieldSchema("binary_vector", milvus::DataType::BINARY_VECTOR).WithDimension(8192));
import { MilvusClient, DataType, FunctionType, IndexType, MetricType } from "@zilliz/milvus2-sdk-node";

const client = new MilvusClient({ address: "YOUR_CLUSTER_ENDPOINT", token: "YOUR_CLUSTER_TOKEN" });

const fields = [
  { name: "id", data_type: DataType.Int64, is_primary_key: true, autoID: true },
  { name: "document_content", data_type: DataType.VarChar, max_length: 9000, enable_analyzer: true },
  { name: "binary_vector", data_type: DataType.BinaryVector, dim: 8192 },
];
fields='[
  {"fieldName": "id", "dataType": "Int64", "isPrimary": true},
  {"fieldName": "document_content", "dataType": "VarChar", "elementTypeParams": {"max_length": 9000, "enable_analyzer": true}},
  {"fieldName": "binary_vector", "dataType": "BinaryVector", "elementTypeParams": {"dim": 8192}}
]'
Define the MinHash function
The MinHash function converts analyzed text into binary vectors that approximate Jaccard similarity between documents.
Define the function and add it to your schema:
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
minhash_function = Function(
    name="minhash_function",
    input_field_names=["document_content"], # Name of the VARCHAR field containing raw text
    output_field_names=["binary_vector"], # Name of the BINARY_VECTOR field for generated signatures
    function_type=FunctionType.MINHASH,
    params={
        "num_hashes": 256, # Number of hash functions; produces dim = 32 * 256 = 8192
        "shingle_size": 3, # N-gram size for shingling
    }
)

schema.add_function(minhash_function)
import io.milvus.common.clientenum.FunctionType;
import io.milvus.v2.service.collection.request.CreateCollectionReq;
import java.util.Collections;

schema.addFunction(CreateCollectionReq.Function.builder()
        .name("minhash_function")
        .functionType(FunctionType.MINHASH)
        .inputFieldNames(Collections.singletonList("document_content"))
        .outputFieldNames(Collections.singletonList("binary_vector"))
        .param("num_hashes", "256")
        .param("shingle_size", "3")
        .build());
import "github.com/milvus-io/milvus/client/v3/entity"

function := entity.NewFunction().
    WithName("minhash_function").
    WithType(entity.FunctionTypeMinHash).
    WithInputFields("document_content").
    WithOutputFields("binary_vector").
    WithParam("num_hashes", "256").
    WithParam("shingle_size", "3")

schema = schema.WithFunction(function)
use milvus::v2::prelude::*;

let schema = schema.add_function(
    Function::new()
        .name("minhash_function")
        .function_type(FunctionType::MinHash)
        .input_fields(vec!["document_content"])
        .output_fields(vec!["binary_vector"])
        .param("num_hashes", "256")
        .param("shingle_size", "3"),
);
auto function = std::make_shared<milvus::Function>("minhash_function", milvus::FunctionType::MINHASH);
function->AddInputFieldName("document_content");
function->AddOutputFieldName("binary_vector");
function->AddParam("num_hashes", "256");
function->AddParam("shingle_size", "3");
schema->AddFunction(function);
import { FunctionType } from "@zilliz/milvus2-sdk-node";

const functions = [
  {
    name: "minhash_function",
    type: FunctionType.MINHASH,
    input_field_names: ["document_content"],
    output_field_names: ["binary_vector"],
    params: { num_hashes: 256, shingle_size: 3 },
  },
];
function='{
  "name": "minhash_function",
  "type": "MinHash",
  "inputFieldNames": ["document_content"],
  "outputFieldNames": ["binary_vector"],
  "params": {"num_hashes": 256, "shingle_size": 3}
}'
Configuration options
The params dictionary of the MinHash function accepts the following parameters. All parameter names are case-insensitive.
Parameter | Type | Default | Description |
|---|---|---|---|
| int | Derived from | Number of hash functions for signature generation. The output binary vector dimension equals |
| int |
| N-gram size for shingling. Word-level: 1-3 is typical. Character-level: 2-6 is typical. |
| str |
| Hash function to use. Options:
|
| str |
| Tokenization level. Options:
Word-level provides stronger semantics and higher efficiency but depends on language-specific tokenization. Character-level is language-agnostic but produces higher-dimensional shingles with weaker semantics. |
| int |
| Random seed for MinHash function initialization. |
Configure the index
The recommended index type for MinHash binary vectors is MINHASH_LSH, with metric type MHJACCARD.
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
index_params = client.prepare_index_params()

index_params.add_index(
    field_name="binary_vector",
    index_type="MINHASH_LSH",
    metric_type="MHJACCARD",
    params={
        "mh_lsh_band": 128,
        "mh_element_bit_width": 32,
        "with_raw_data": True,
    },
)
import io.milvus.v2.common.IndexParam;
import java.util.HashMap;

IndexParam indexParam = IndexParam.builder()
        .fieldName("binary_vector")
        .indexType(IndexParam.IndexType.MINHASH_LSH)
        .metricType(IndexParam.MetricType.MHJACCARD)
        .extraParams(new HashMap<String, Object>() {{
            put("mh_lsh_band", 128);
            put("mh_element_bit_width", 32);
            put("with_raw_data", true);
        }})
        .build();
import (
    "github.com/milvus-io/milvus/client/v3/entity"

    "github.com/milvus-io/milvus/client/v3/index"
    "github.com/milvus-io/milvus/client/v3/milvusclient"
)

indexOption := milvusclient.NewCreateIndexOption("dedup_collection", "binary_vector", index.NewMinHashLSHIndex(entity.MHJACCARD, 128).
    WithElementBitWidth(32).
    WithRawData(true)).
    WithIndexName("minhash_index")
use milvus::v2::prelude::*;
use std::collections::HashMap;

let index_param = IndexParam::new()
    .field_name("binary_vector")
    .index_name("minhash_index")
    .index_type(IndexType::MinhashLsh)
    .metric_type(MetricType::MhJaccard)
    .extra_params(HashMap::from([
        ("mh_lsh_band".to_string(), "128".to_string()),
        ("mh_element_bit_width".to_string(), "32".to_string()),
        ("with_raw_data".to_string(), "true".to_string()),
    ]));
milvus::IndexDesc index("binary_vector", "minhash_index", milvus::IndexType::MINHASH_LSH, milvus::MetricType::MHJACCARD);
index.AddExtraParam("mh_lsh_band", "128");
index.AddExtraParam("mh_element_bit_width", "32");
index.AddExtraParam("with_raw_data", "true");
import { IndexType, MetricType } from "@zilliz/milvus2-sdk-node";

const indexParam = {
  field_name: "binary_vector",
  index_type: IndexType.MINHASH_LSH,
  metric_type: MetricType.MHJACCARD,
  params: { mh_lsh_band: 128, mh_element_bit_width: 32, with_raw_data: true },
};
indexParams='[
  {"fieldName": "binary_vector", "indexType": "MINHASH_LSH", "metricType": "MHJACCARD", "params": {"mh_lsh_band": 128, "mh_element_bit_width": 32, "with_raw_data": true}}
]'
Set with_raw_data to True if searches will use Jaccard refinement. The raw MinHash signatures are required to calculate estimated Jaccard similarity for the candidates returned by the LSH lookup.
Create the collection
Create the collection using the schema and index parameters defined above:
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
client.create_collection(
    collection_name="dedup_collection",
    schema=schema,
    index_params=index_params,
)
import io.milvus.v2.service.collection.request.CreateCollectionReq;
import java.util.Collections;

client.createCollection(CreateCollectionReq.builder()
        .collectionName("dedup_collection")
        .collectionSchema(schema)
        .indexParams(Collections.singletonList(indexParam))
        .build());
import (
    "log"

    "github.com/milvus-io/milvus/client/v3/milvusclient"
)

err = client.CreateCollection(ctx, milvusclient.NewCreateCollectionOption("dedup_collection", schema).
    WithIndexOptions(indexOption))
if err != nil {
    log.Fatal(err)
}
use milvus::v2::prelude::*;

client.create_collection(CreateCollectionRequest::builder()
    .collection_name("dedup_collection")
    .schema(schema)
    .index_params(vec![index_param])
    .build()?)
.await?;
status = client->CreateCollection(milvus::CreateCollectionRequest()
                                 .WithCollectionName("dedup_collection")
                                 .WithCollectionSchema(schema));
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
await client.createCollection({
  collection_name: "dedup_collection",
  fields: fields,
  functions: functions,
});

await client.createIndex({
  collection_name: "dedup_collection",
  ...indexParam,
});
export CLUSTER_ENDPOINT="YOUR_CLUSTER_ENDPOINT"
export TOKEN="YOUR_CLUSTER_TOKEN"

curl --request POST \
--url "${CLUSTER_ENDPOINT}/v2/vectordb/collections/create" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
-d '{
    "collectionName": "dedup_collection",
    "schema": {
        "fields": [
            {"fieldName": "id", "dataType": "Int64", "isPrimary": true},
            {"fieldName": "document_content", "dataType": "VarChar", "elementTypeParams": {"max_length": 9000, "enable_analyzer": true}},
            {"fieldName": "binary_vector", "dataType": "BinaryVector", "elementTypeParams": {"dim": 8192}}
        ],
        "functions": [
            {"name": "minhash_function", "type": "MinHash", "inputFieldNames": ["document_content"], "outputFieldNames": ["binary_vector"], "params": {"num_hashes": 256, "shingle_size": 3}}
        ],
        "autoID": true
    },
    "indexParams": [
        {"fieldName": "binary_vector", "indexType": "MINHASH_LSH", "metricType": "MHJACCARD", "params": {"mh_lsh_band": 128, "mh_element_bit_width": 32, "with_raw_data": true}}
    ]
}'
Step 2: Insert documents
After setting up your collection, insert text data. You only need to provide the raw text — the MinHash function automatically generates the binary vector for each document.
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
client.insert(
    "dedup_collection",
    [
        {"document_content": "information retrieval is a field of study that helps users find relevant information in large datasets"},
        {"document_content": "information retrieval is a research field focused on helping users find relevant data in large collections"},
        {"document_content": "information retrieval is a field of research helping users search for relevant information in large datasets"},
    ],
)
import com.google.gson.JsonObject;
import io.milvus.v2.service.vector.request.InsertReq;
import java.util.ArrayList;
import java.util.List;

List<JsonObject> data = new ArrayList<>();

JsonObject row1 = new JsonObject();
row1.addProperty("document_content", "information retrieval is a field of study that helps users find relevant information in large datasets");
data.add(row1);

JsonObject row2 = new JsonObject();
row2.addProperty("document_content", "information retrieval is a research field focused on helping users find relevant data in large collections");
data.add(row2);

JsonObject row3 = new JsonObject();
row3.addProperty("document_content", "information retrieval is a field of research helping users search for relevant information in large datasets");
data.add(row3);

client.insert(InsertReq.builder()
        .collectionName("dedup_collection")
        .data(data)
        .build());
import (
    "log"

    "github.com/milvus-io/milvus/client/v3/milvusclient"
)

_, err = client.Insert(ctx, milvusclient.NewColumnBasedInsertOption("dedup_collection").
    WithVarcharColumn("document_content", []string{
        "information retrieval is a field of study that helps users find relevant information in large datasets",
        "information retrieval is a research field focused on helping users find relevant data in large collections",
        "information retrieval is a field of research helping users search for relevant information in large datasets",
    }))
if err != nil {
    log.Fatal(err)
}
use milvus::v2::prelude::*;
use serde_json::json;

let insert_req = InsertRequest::builder()
    .collection_name("dedup_collection")
    .rows(vec![
        json!({"document_content": "information retrieval is a field of study that helps users find relevant information in large datasets"}),
        json!({"document_content": "information retrieval is a research field focused on helping users find relevant data in large collections"}),
        json!({"document_content": "information retrieval is a field of research helping users search for relevant information in large datasets"}),
    ])
    .build()?;

client.insert(insert_req).await?;
milvus::EntityRows rows;
rows.emplace_back(milvus::EntityRow{{"document_content", "information retrieval is a field of study that helps users find relevant information in large datasets"}});
rows.emplace_back(milvus::EntityRow{{"document_content", "information retrieval is a research field focused on helping users find relevant data in large collections"}});
rows.emplace_back(milvus::EntityRow{{"document_content", "information retrieval is a field of research helping users search for relevant information in large datasets"}});

milvus::InsertResponse insert_response;
status = client->Insert(milvus::InsertRequest()
                            .WithCollectionName("dedup_collection")
                            .WithRowsData(std::move(rows)),
                        insert_response);
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
await client.insert({
  collection_name: "dedup_collection",
  data: [
    { document_content: "information retrieval is a field of study that helps users find relevant information in large datasets" },
    { document_content: "information retrieval is a research field focused on helping users find relevant data in large collections" },
    { document_content: "information retrieval is a field of research helping users search for relevant information in large datasets" },
  ],
});
export CLUSTER_ENDPOINT="YOUR_CLUSTER_ENDPOINT"
export TOKEN="YOUR_CLUSTER_TOKEN"

curl --request POST \
--url "${CLUSTER_ENDPOINT}/v2/vectordb/entities/insert" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
-d '{
    "collectionName": "dedup_collection",
    "data": [
        {"document_content": "information retrieval is a field of study that helps users find relevant information in large datasets"},
        {"document_content": "information retrieval is a research field focused on helping users find relevant data in large collections"},
        {"document_content": "information retrieval is a field of research helping users search for relevant information in large datasets"}
    ]
}'
Step 3: Search with MinHash
Once you have inserted data, search for near-duplicate documents by providing raw text queries. Zilliz Cloud automatically converts each query into a MinHash binary vector. Enable Jaccard refinement to rank the LSH candidates by estimated Jaccard similarity.
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- cURL
search_params = {
    "metric_type": "MHJACCARD",
    "params": {
        "mh_search_with_jaccard": True,
        "refine_k": 3,
    },
}

results = client.search(
    collection_name="dedup_collection",
    data=["information retrieval is a research field focused on helping users find relevant data in large collections"],
    anns_field="binary_vector",
    limit=3,
    output_fields=["document_content"],
    search_params=search_params,
)

for hits in results:
    for hit in hits:
        print(f"ID: {hit['id']}, Distance: {hit['distance']}")
        print(f"Document: {hit['entity']['document_content']}")
import io.milvus.v2.service.vector.request.SearchReq;
import io.milvus.v2.service.vector.request.data.EmbeddedText;
import io.milvus.v2.service.vector.response.SearchResp;
import io.milvus.v2.common.IndexParam;
import java.util.Arrays;
import java.util.Collections;
import java.util.HashMap;

SearchResp resp = client.search(SearchReq.builder()
        .collectionName("dedup_collection")
        .annsField("binary_vector")
        .data(Collections.singletonList(new EmbeddedText("information retrieval is a research field focused on helping users find relevant data in large collections")))
        .metricType(IndexParam.MetricType.MHJACCARD)
        .searchParams(new HashMap<String, Object>() {{
            put("mh_search_with_jaccard", true);
            put("refine_k", 3);
        }})
        .limit(3)
        .outputFields(Collections.singletonList("document_content"))
        .build());

for (SearchResp.SearchResult hit : resp.getSearchResults().get(0)) {
    System.out.println("ID: " + hit.getEntity().get("id") + ", Distance: " + hit.getScore());
    System.out.println("Document: " + hit.getEntity().get("document_content"));
}
import (
    "fmt"
    "log"

    "github.com/milvus-io/milvus/client/v3/entity"
    "github.com/milvus-io/milvus/client/v3/milvusclient"
)

results, err := client.Search(ctx, milvusclient.NewSearchOption(
    "dedup_collection", 3,
    []entity.Vector{entity.Text("information retrieval is a research field focused on helping users find relevant data in large collections")}).
    WithANNSField("binary_vector").
    WithOutputFields("document_content").
    WithSearchParam("metric_type", "MHJACCARD").
    WithSearchParam("mh_search_with_jaccard", "true").
    WithSearchParam("refine_k", "3"))
if err != nil {
    log.Fatal(err)
}

for _, rs := range results {
    fmt.Printf("ID: %v, Distance: %v\n", rs.IDs, rs.Scores)
}
use milvus::v2::prelude::*;
use std::collections::HashMap;

let search_req = SearchRequest::builder()
    .collection_name("dedup_collection")
    .vector_field("binary_vector")
    .vectors(SearchVectors::EmbeddedText(vec!["information retrieval is a research field focused on helping users find relevant data in large collections".to_string()]))
    .metric_type(MetricType::MhJaccard)
    .extra_params(HashMap::from([
        ("mh_search_with_jaccard".to_string(), "true".to_string()),
        ("refine_k".to_string(), "3".to_string()),
    ]))
    .output_fields(vec!["document_content"])
    .limit(3)
    .build()?;

let res = client.search(search_req).await?;
println!("{:?}", res.results());
milvus::SearchResponse response;
status = client->Search(milvus::SearchRequest()
                            .WithCollectionName("dedup_collection")
                            .WithAnnsField("binary_vector")
                            .AddEmbeddedText("information retrieval is a research field focused on helping users find relevant data in large collections")
                            .WithMetricType(milvus::MetricType::MHJACCARD)
                            .AddExtraParam("mh_search_with_jaccard", "true")
                            .AddExtraParam("refine_k", "3")
                            .WithLimit(3)
                            .AddOutputField("document_content"),
                        response);
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
const results = await client.search({
  collection_name: "dedup_collection",
  anns_field: "binary_vector",
  data: ["information retrieval is a research field focused on helping users find relevant data in large collections"],
  output_fields: ["document_content"],
  search_params: {
    metric_type: "MHJACCARD",
    topk: 3,
    params: JSON.stringify({ mh_search_with_jaccard: true, refine_k: 3 }),
  },
});
console.log(results);
export CLUSTER_ENDPOINT="YOUR_CLUSTER_ENDPOINT"
export TOKEN="YOUR_CLUSTER_TOKEN"

curl --request POST \
--url "${CLUSTER_ENDPOINT}/v2/vectordb/entities/search" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
-d '{
    "collectionName": "dedup_collection",
    "annsField": "binary_vector",
    "data": ["information retrieval is a research field focused on helping users find relevant data in large collections"],
    "limit": 3,
    "outputFields": ["document_content"],
    "searchParams": {"metric_type": "MHJACCARD", "params": {"mh_search_with_jaccard": true, "refine_k": 3}}
}'
Set mh_search_with_jaccard to True to enable Jaccard refinement. refine_k controls the candidate-pool capacity used for refinement. Zilliz Cloud uses max(refine_k, limit) as the capacity, but may refine fewer candidates if the LSH lookup returns fewer matches. Increasing refine_k can improve result quality at the cost of additional computation.
What's next
-
Full Text Search: Use BM25 for lexical relevance ranking instead of near-duplicate detection.
-
Analyzer Overview: Configure custom analyzers for text tokenization.
-
MINHASH_LSH Index: Learn about tuning LSH parameters for recall and performance.