Zero Downtime Migration
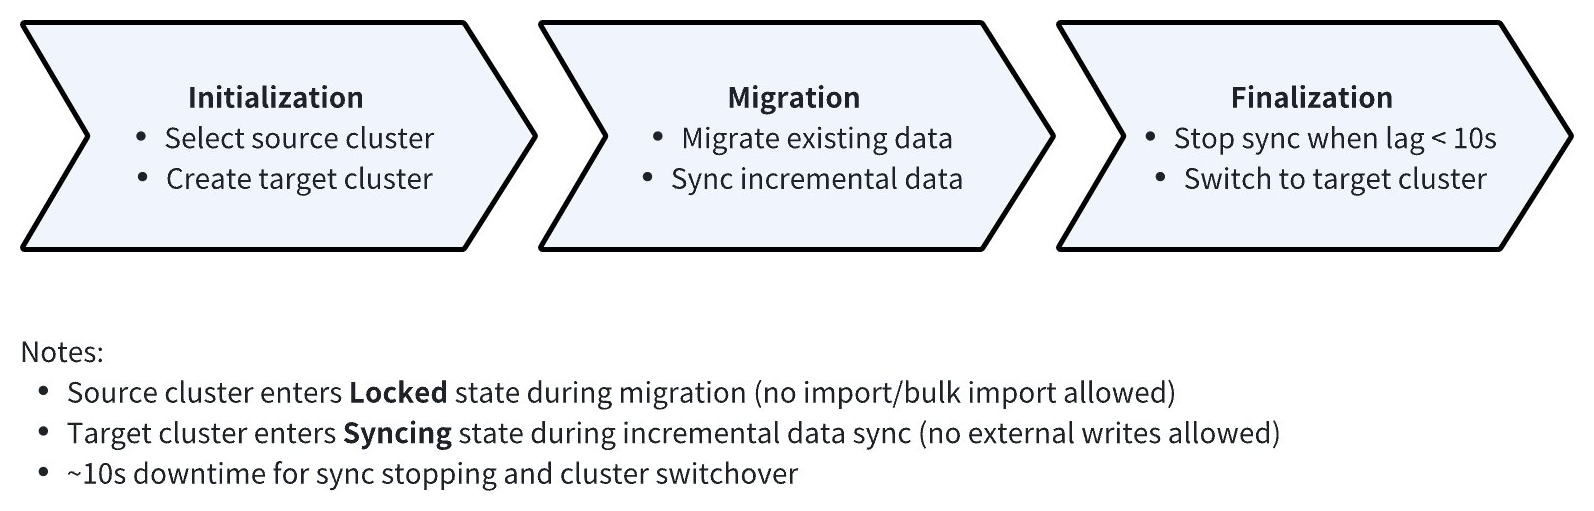
On RequestZero Downtime Migration keeps the source cluster available while copying existing data and syncing incremental changes to a target cluster. Completing the migration requires stopping source services and writes before switching your application. It consists of these stages:
-
Initialization: Select a source database and the collections to migrate, then select a database in an existing target cluster.
-
Migration: Migrate existing data and sync incremental data.
-
Finalization: Stop services and writes to the source cluster, then stop data sync when sync lag is below 10 seconds. After migration completes, manually load the migrated collections and switch your application to the target cluster.
Zero Downtime Migration is available in Private Preview. Contact Zilliz Cloud support to request access. The supported Milvus version requirement for the source and target clusters is ≥ 2.6.21 or ≥ 3.0.0. The target cluster version must not be lower than the source cluster version.
Migration capabilities
Cluster compatibility
The following table outlines the migration capabilities and constraints between clusters:
| Source Cluster | Target Cluster | Migration Scope |
|---|---|---|
| Dedicated | Dedicated cluster | Select a source database and migrate all or selected collections to a database in an existing target Dedicated cluster. |
| Serverless / Free | Dedicated cluster | Migrate a single database from the source cluster, as Serverless/Free clusters contain at most one database. |
Migration scope options
| Migration Type | Description | Use Cases |
|---|---|---|
| Within same project | Migrate between existing clusters in the same Zilliz Cloud project | Cluster upgrades, performance optimization, data consolidation |
| Cross-project within the same organization | Migrate between existing clusters in different projects within the same Zilliz Cloud organization. Cross-organization migration is not currently supported. | Move data between projects within an organization |
Direct data transfer
Zero Downtime Migration performs direct data replication between Zilliz Cloud clusters with the following characteristics:
-
Schema preservation: Source schema transferred unchanged to target cluster
-
No field transformations: The migration does not rename fields, change data types, or modify field attributes. Avoid changing the schema of the selected collections during incremental sync, as these changes are not replicated.
-
Automatic indexing: AUTOINDEX automatically created for vector fields in target cluster
Limits
-
During incremental sync, only Delete, Insert, and Upsert operations on the selected source collections are replicated. Avoid other changes to these collections, including schema changes and bulk imports, because they are not replicated and can cause data inconsistencies.
-
Avoid direct writes to the target collections being migrated, as they can cause data inconsistencies.
-
Keep the source cluster until migration completes. Deleting it while migration is in progress causes migration errors.
-
For source collections that have AutoID enabled, enable Allow Insert AutoID before migration. Otherwise, the migration will not be dispatched.
-
The result of
count(*)on the target collection after the migration might differ from that of the source collection due to retries caused by network instabilities.
Prerequisites
Before starting your zero downtime migration, ensure you meet these requirements:
General requirements
| Requirement | Details |
|---|---|
| User permissions | You need SERVING_CLUSTER_DATA_READ on the source cluster, SERVING_CLUSTER_DATA_WRITE on the target cluster, and OBSERVABILITY_MANAGE on the relevant project. For simpler permission setup, use the Project Admin role. |
| Source cluster access | You do not need to enable public internet access to the source cluster. Migration uses private network connectivity. |
| Target cluster capacity | Ensure the target cluster has sufficient CU capacity to accommodate the source data (use the CU calculator). If capacity is insufficient during migration, increase capacity and contact Zilliz Cloud support for assistance with continuing the migration. |
Authentication and AutoID requirements
Select the source and target clusters in the console. Access is checked against your current permissions; you do not need to enter a source endpoint, API key, or cluster username and password for the migration. The source and target must belong to the same organization.
For collections with AutoID enabled, allow_insert_auto_id must be enabled before incremental migration.
Getting started
The zero downtime migration process consists of three main phases that require your attention and action:
Phase 1: Initialize
Start from the organization and project that contain your target cluster. The following demo shows how to select the source data and target location and start the migration:
-
In the target project, select Migrations in the left navigation. Under Zilliz to Zilliz Migration, click Zero Downtime.
-
Click Select Source Location and select the source Organization, Project, Cluster, and Database. The source and target must belong to the same organization.
-
Select the collections to migrate. Keep All Collections selected to migrate all collections in the selected database, or select individual collections.
-
Click Select Target Location and select the target cluster and database. The target organization and project are set to your Current Location.
-
Review the source and target locations and the Selected Collections list, then click Migrate.
During migration, the source cluster remains in the Running state, and the target cluster displays Migrating. Keep the source cluster until migration completes; deleting it during migration causes migration errors.
Phase 2: Monitor
On the target cluster details page, click View Progress in the migration banner to open the Migration Progress dialog. Use this dialog to monitor existing data migration and incremental data syncing, then stop data sync when you are ready to switch your application.
You can also monitor the job from Jobs. Open the migration job's actions menu, select View Details, and select the Data tab to view Rows Written, Sync Delay, Data Synced Through, Metrics Updated, and the source-to-target collection mappings.
Stage 1: Migrate existing data
The Migrate Existing Data stage copies the existing data from the selected source collections to the target database. The duration depends on the volume of data being transferred and may take several hours for large datasets.
If the process is taking a while, feel free to leave this page and work on other tasks. You can return at any time to continue monitoring the incremental data syncing progress.
Stage 2: Sync incremental data
During Sync incremental data, the system continuously replicates Delete, Insert, and Upsert operations on the selected source collections to the target cluster. The target cluster remains in the Migrating state. To avoid data inconsistencies, do not make other changes to the selected source collections or write directly to the target collections being migrated. Follow these steps to complete synchronization:
-
Monitor sync lag
-
Track the Lag Behind Source (displayed in milliseconds or seconds) to monitor sync progress. This indicator shows the time difference between the most recent data in the source and target clusters.
-
When the Lag Behind Source drops below 10s, you'll receive an email notification indicating you can proceed with stopping data sync.
-
Important: If the sync lag does not drop below 10 seconds after a reasonable waiting period, contact Zilliz Cloud support.
-
-
Stop data sync
-
Stop services and all writes to the source cluster. Keep writes stopped while stopping data sync and switching your application to the target cluster.
-
When Lag Behind Source is less than 10 seconds and source writes have stopped, select I confirm that I have stopped writes to the source cluster, then click Stop Data Sync. This is the normal cutover path. After it completes, the migration job displays Success.
NotesIncremental sync is supported for up to 7 days. Plan to complete your migration within this period. If you need more time, contact Zilliz Cloud support.
-
Phase 3: Switch
After you click Stop Data Sync, wait for the migration to complete before switching your application to the target cluster. The email notification that sync lag is below 10 seconds indicates that you can prepare to stop data sync; it does not mean that migration has completed.
-
Wait for the migration to complete in the Migration Progress dialog. The completed migration job displays Success.
-
Click View Connection Details And Close Dialog to view the target cluster's connection details.
-
Manually load the migrated collections before search or query operations, as described below. Update the endpoint and credentials in your application code to connect to the target cluster, then verify that the application can read and write data.
For instructions on connecting to a cluster, refer to Connect to Cluster.
-
After migration, the source cluster will not be deleted automatically. We recommend keeping it for a period to verify data consistency before manual deletion.
-
The migrated collections are not immediately available for search or query operations. You must manually load the collections in Zilliz Cloud to enable search and query functionalities. For details, refer to Load & Release.
Cancel a migration
To abandon a migration, open Jobs, locate the migration job, and select Cancel from its actions menu where available. Canceling stops synchronization and changes the job status to Canceled. Data already synchronized to the target is not automatically removed; review and handle that data as needed.
Use Stop Data Sync in the Migration Progress dialog to complete the migration before switching your application. The completed job displays Success. Use Cancel to abandon the migration; the job displays Canceled.