Use Partition Key
The Partition Key is a search optimization solution that enables logical data isolation by serving as a namespace for your collection. By designating a specific scalar field (such as a tenant ID or project name) as the Partition Key, you can effectively segment data into distinct namespaces within a single collection. This allows search requests to be scoped to a specific namespace via filtering conditions, significantly narrowing the search range and improving overall efficiency. This article introduces how to implement this namespace-based optimization and the considerations for using the Partition Key.
Overview
In Zilliz Cloud, you can use partitions to implement data segregation and improve search performance by restricting the search scope to specific partitions. If you choose to manage partitions manually, you can create a maximum of 1,024 partitions in a collection, and insert entities into these partitions based on a specific rule so that you can narrow the search scope by restricting searches within a specific number of partitions.
Zilliz Cloud introduces the Partition Key for you to reuse partitions in data segregation to overcome the limit on the number of partitions you can create in a collection. When creating a collection, you can use a scalar field as the Partition Key. Once the collection is ready, Zilliz Cloud creates the specified number of partitions inside the collection. Upon receiving an inserted entity, Zilliz Cloud calculates a hash value using the Partition Key value of the entity, executes a modulo operation based on the hash value and the partitions_num property of the collection to obtain the target partition ID, and stores the entity in the target partition.
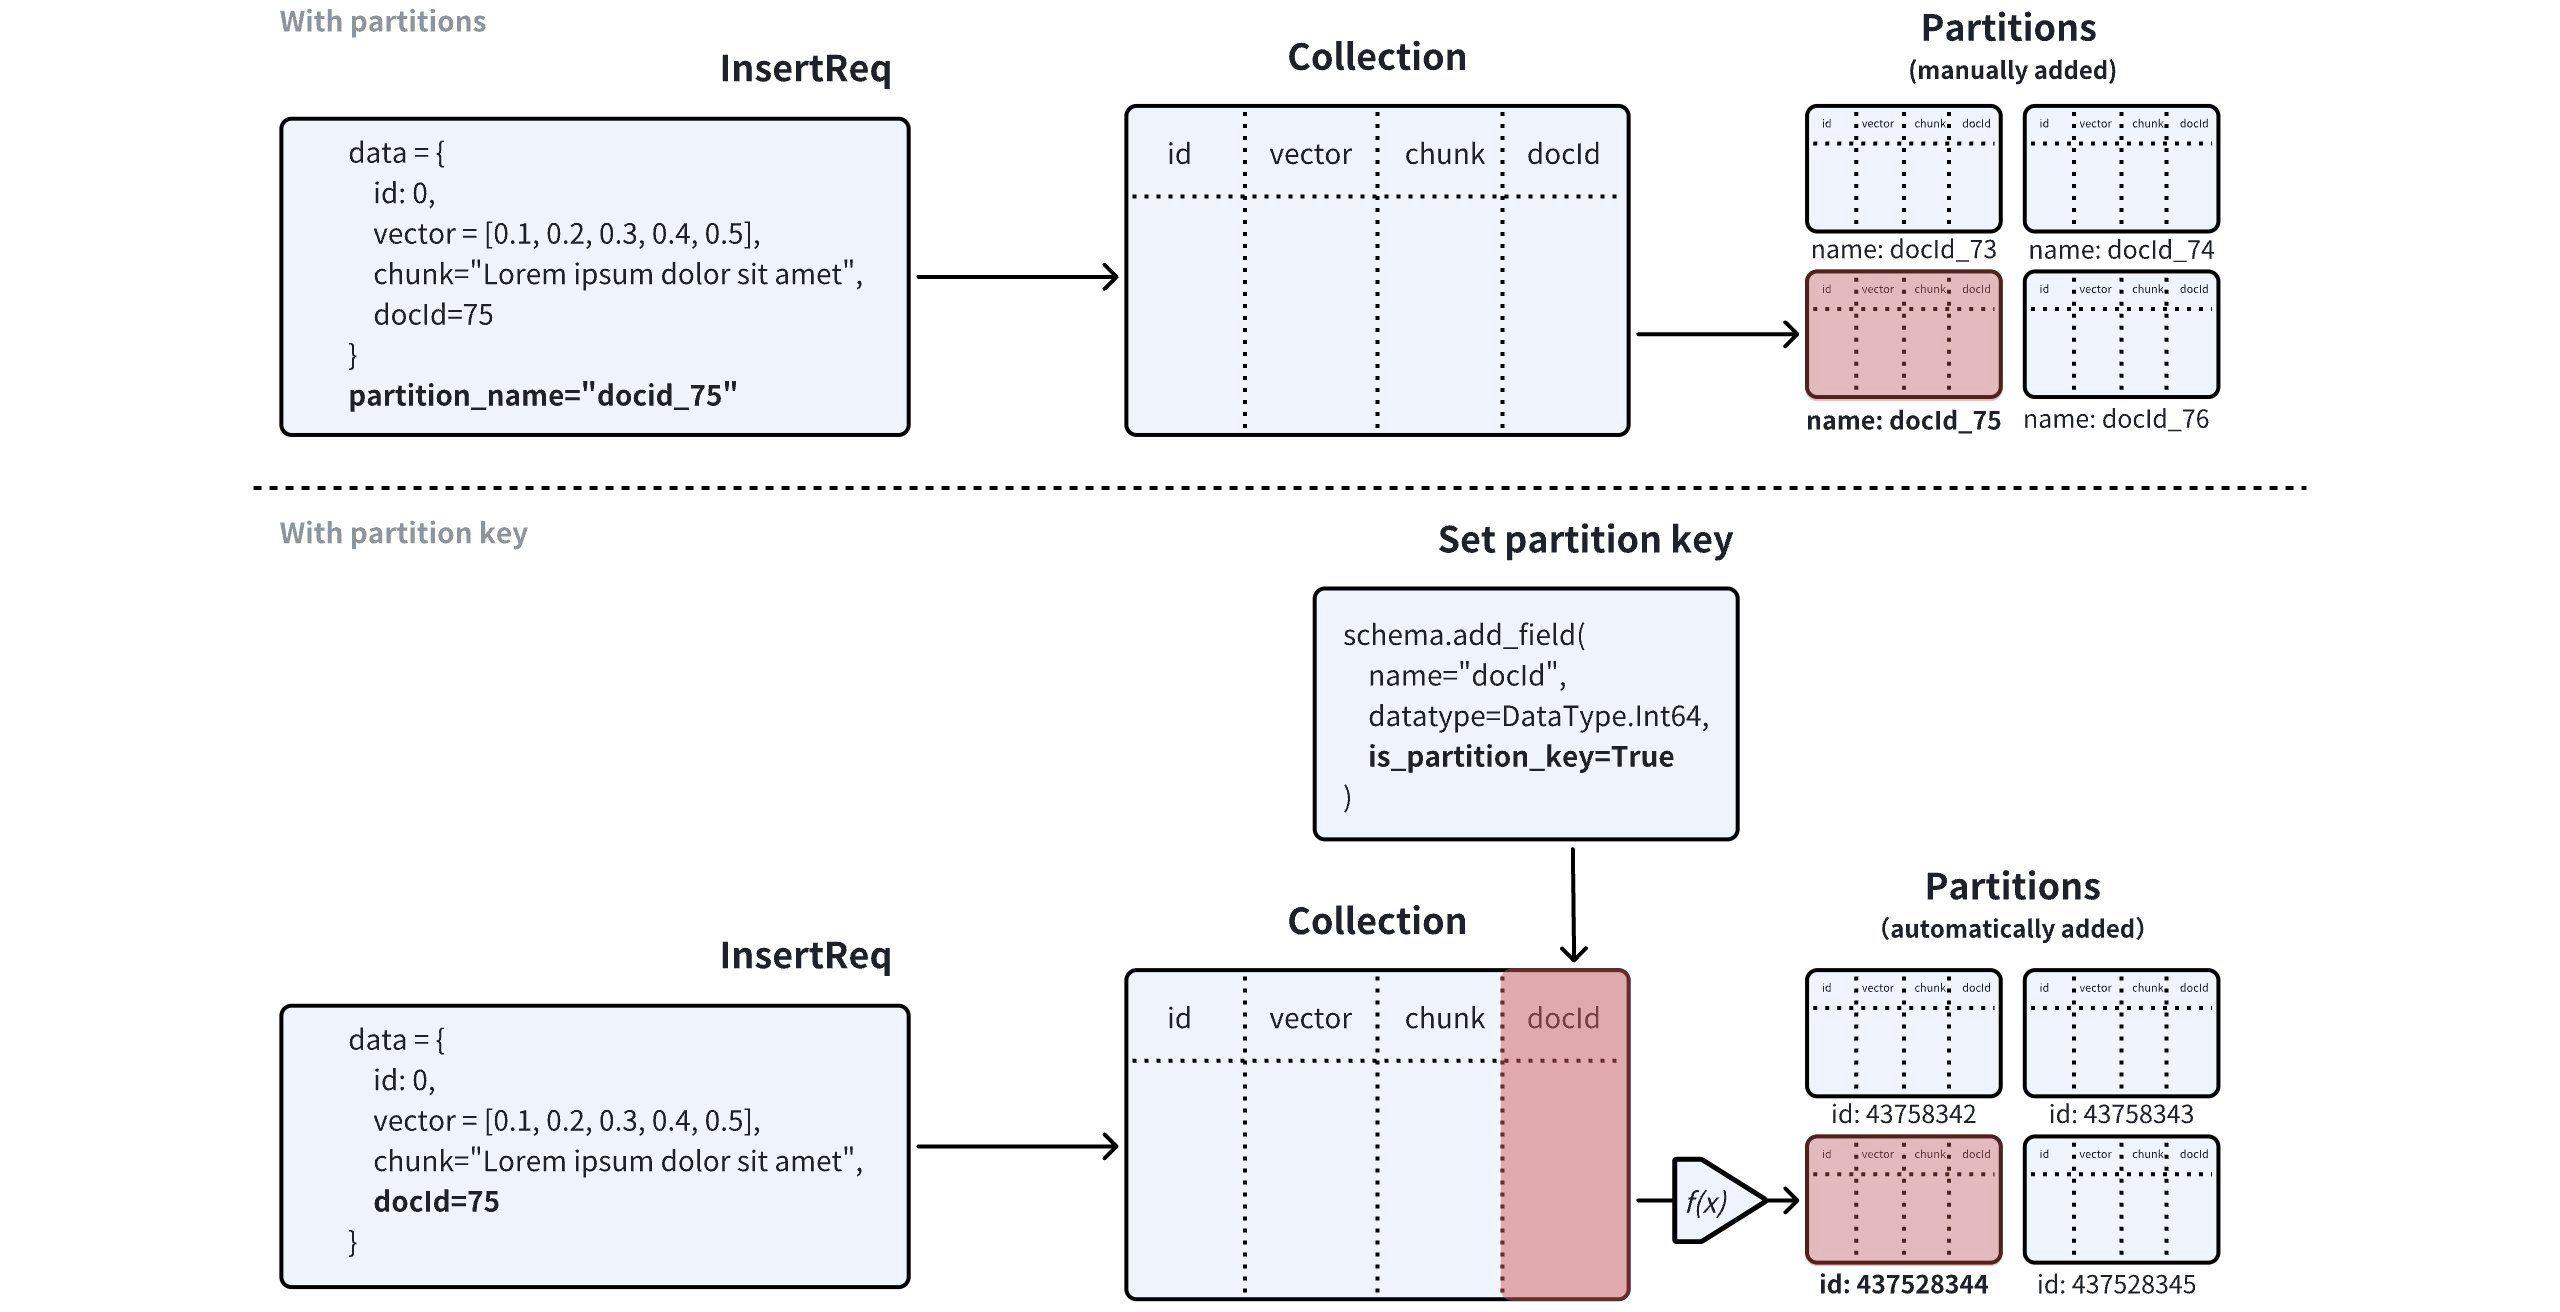
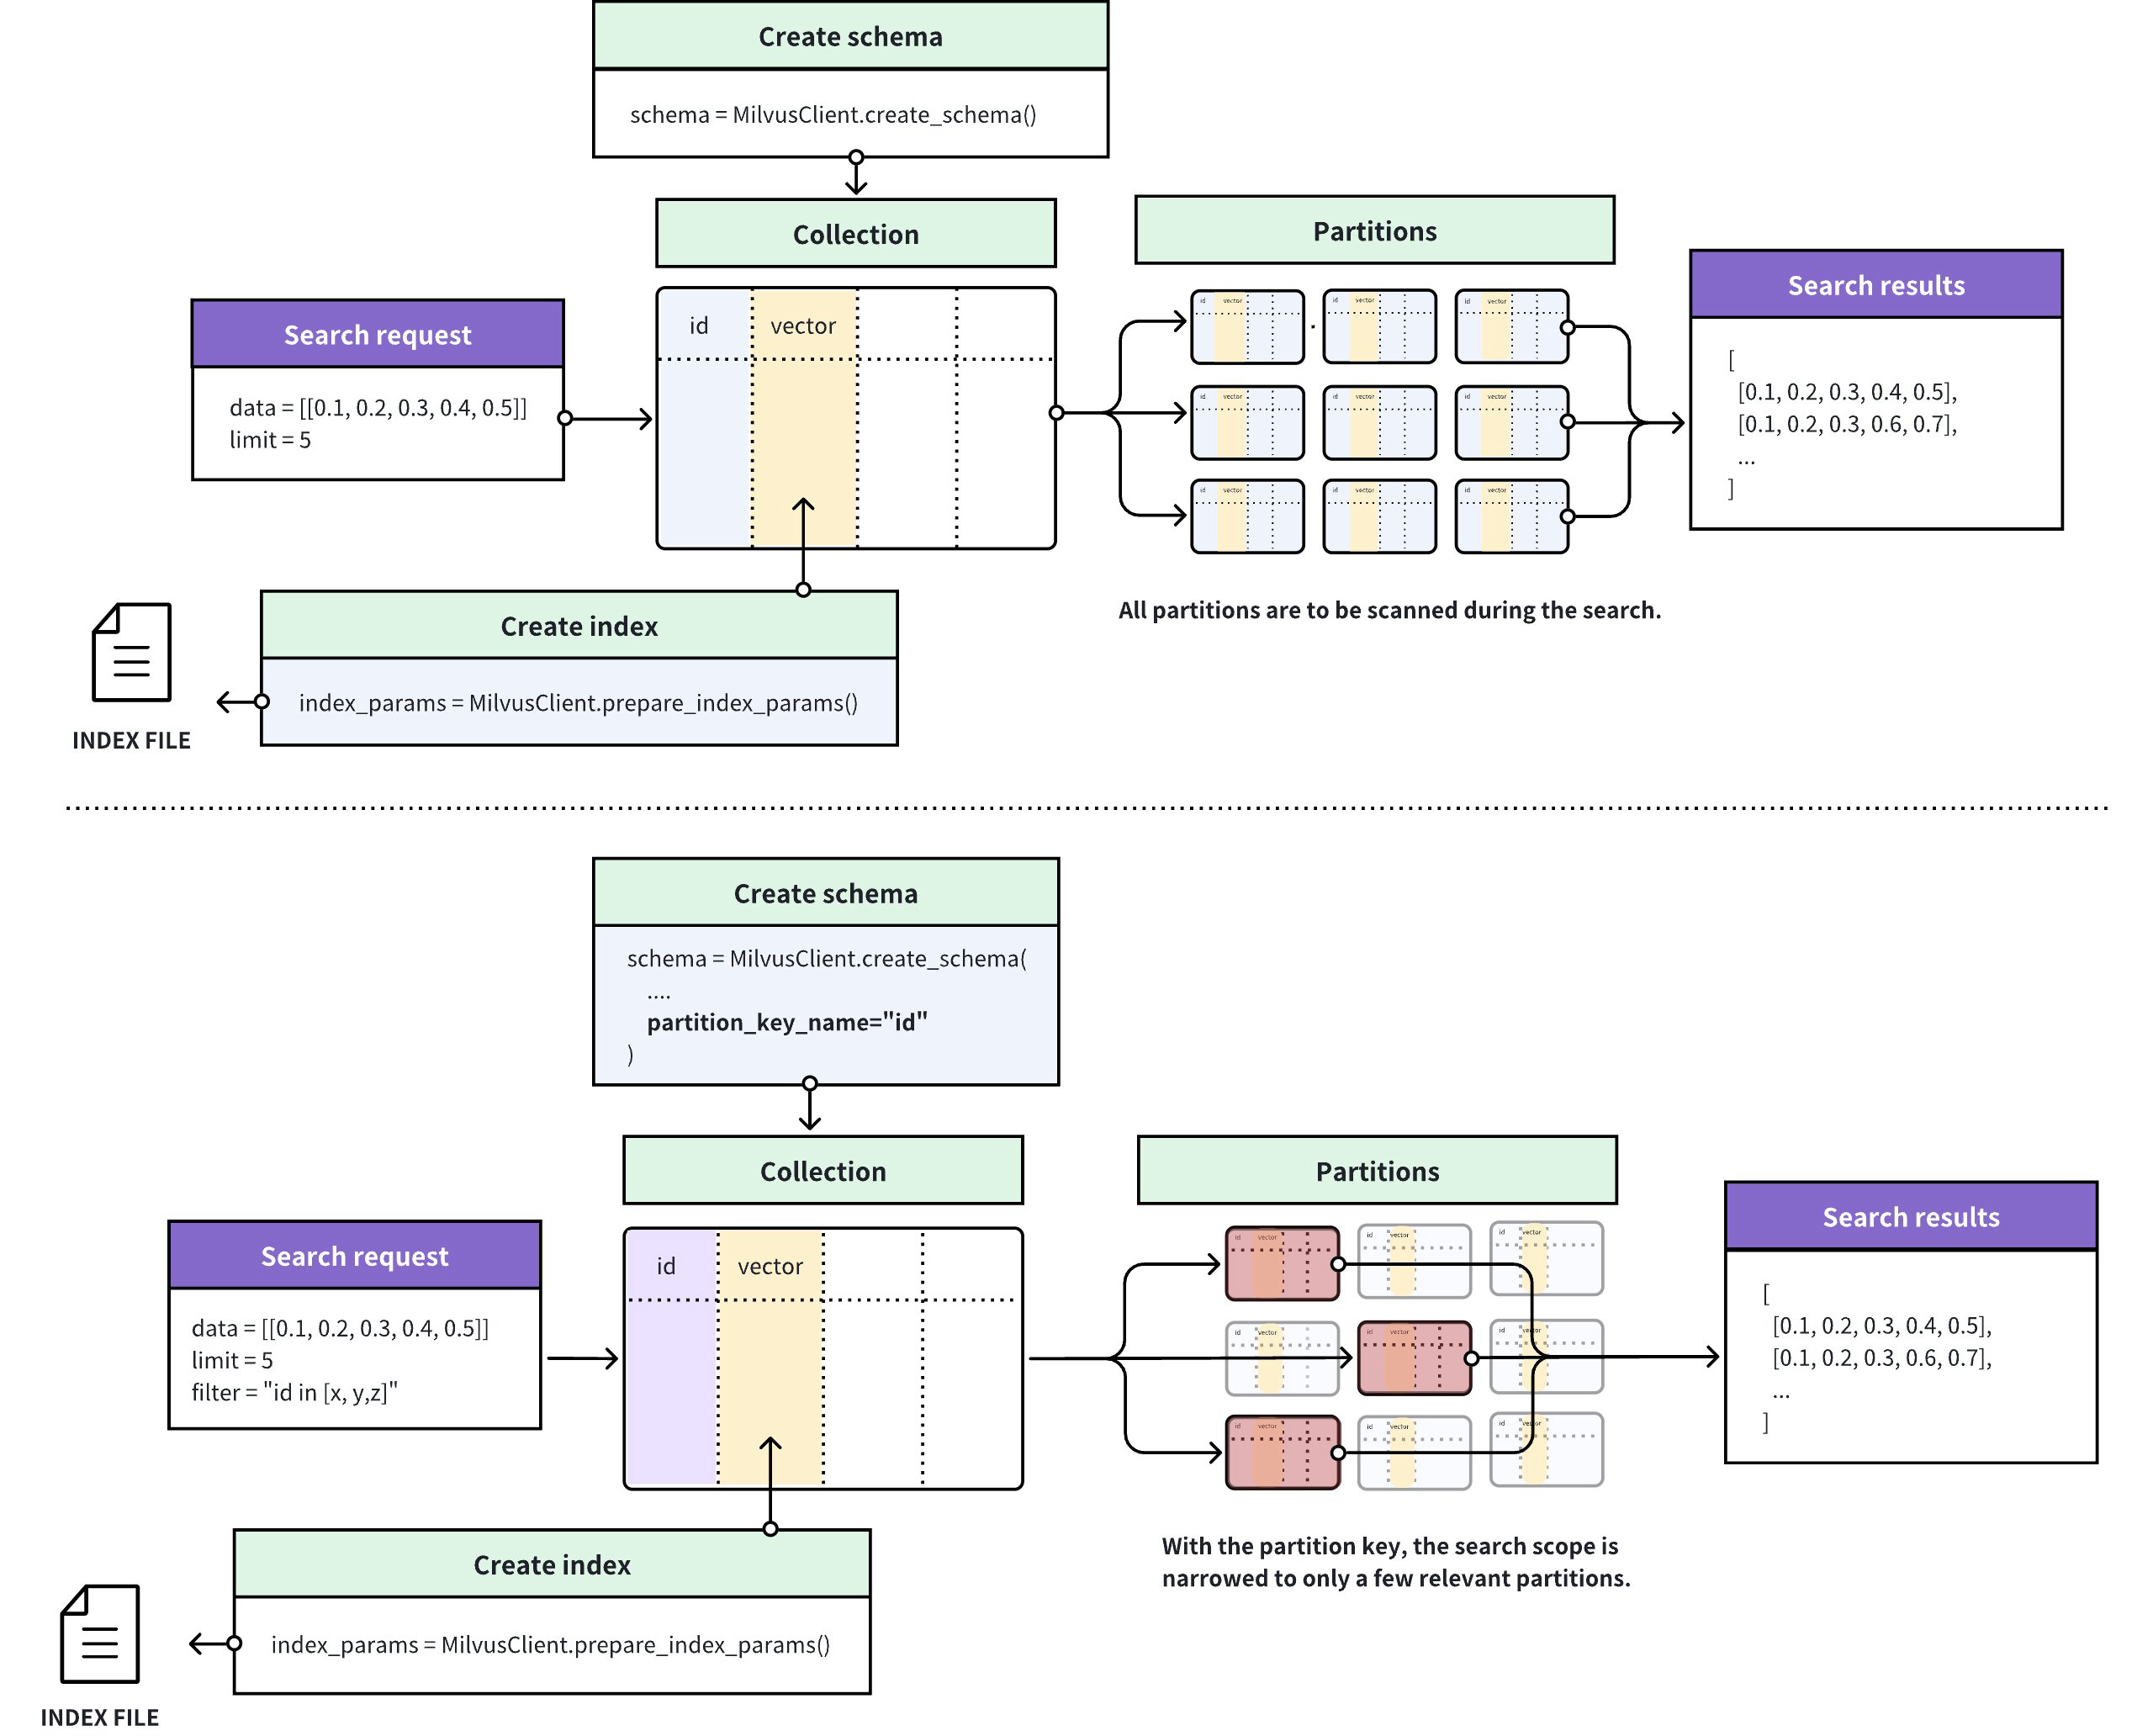
The following figure illustrates how Zilliz Cloud processes the search requests in a collection with or without the Partition Key feature enabled.
-
If the Partition Key is disabled, Zilliz Cloud searches for entities that are the most similar to the query vector within the collection. You can narrow the search scope if you know which partition contains the most relevant results.
-
If the Partition Key is enabled, Zilliz Cloud determines the search scope based on the Partition Key value specified in a search filter and scans only the entities within the partitions that match.
Use Partition Key
To use the Partition Key, you need to
-
Set the number of partitions to create (Optional),
-
Create a filtering condition based on the Partition Key, and
-
Index the Partition Key (Recommended).
Set Partition Key
To designate a scalar field as the Partition Key, you need to set its is_partition_key attribute to true when you add the scalar field.
When you set a scalar field as the Partition Key, the field values cannot be empty or null.
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- CSharp
- cURL
from pymilvus import (
    MilvusClient, DataType
)

client = MilvusClient(
    uri="YOUR_CLUSTER_ENDPOINT",
    token="YOUR_CLUSTER_TOKEN"
)

schema = client.create_schema()

schema.add_field(field_name="id",
    datatype=DataType.INT64,
    is_primary=True)

schema.add_field(field_name="vector",
    datatype=DataType.FLOAT_VECTOR,
    dim=5)

# Add the partition key
schema.add_field(
    field_name="my_varchar",
    datatype=DataType.VARCHAR,
    max_length=512,
    is_partition_key=True,
)
import io.milvus.v2.client.ConnectConfig;
import io.milvus.v2.client.MilvusClientV2;
import io.milvus.v2.common.DataType;
import io.milvus.v2.service.collection.request.AddFieldReq;
import io.milvus.v2.service.collection.request.CreateCollectionReq;

MilvusClientV2 client = new MilvusClientV2(ConnectConfig.builder()
        .uri("YOUR_CLUSTER_ENDPOINT")
        .token("YOUR_CLUSTER_TOKEN")
        .build());

// Create schema
CreateCollectionReq.CollectionSchema schema = client.createSchema();

schema.addField(AddFieldReq.builder()
        .fieldName("id")
        .dataType(DataType.Int64)
        .isPrimaryKey(true)
        .build());

schema.addField(AddFieldReq.builder()
        .fieldName("vector")
        .dataType(DataType.FloatVector)
        .dimension(5)
        .build());

// Add the partition key
schema.addField(AddFieldReq.builder()
        .fieldName("my_varchar")
        .dataType(DataType.VarChar)
        .maxLength(512)
        .isPartitionKey(true)
        .build());
import (
    "context"
    "fmt"

    "github.com/milvus-io/milvus/client/v3/entity"
    "github.com/milvus-io/milvus/client/v3/milvusclient"
)

ctx, cancel := context.WithCancel(context.Background())
defer cancel()

milvusAddr := "YOUR_CLUSTER_ENDPOINT"
client, err := milvusclient.New(ctx, &milvusclient.ClientConfig{
    Address: milvusAddr,
    APIKey:  "YOUR_CLUSTER_TOKEN",
})
if err != nil {
    fmt.Println(err.Error())
    // handle error
}
defer client.Close(ctx)

schema := entity.NewSchema().WithDynamicFieldEnabled(false)
schema.WithField(entity.NewField().
    WithName("id").
    WithDataType(entity.FieldTypeInt64).
    WithIsPrimaryKey(true),
).WithField(entity.NewField().
    WithName("my_varchar").
    WithDataType(entity.FieldTypeVarChar).
    WithIsPartitionKey(true).
    WithMaxLength(512),
).WithField(entity.NewField().
    WithName("vector").
    WithDataType(entity.FieldTypeFloatVector).
    WithDim(5),
)
use milvus::v2::prelude::*;

let config = ConnectConfig::new()
    .uri("YOUR_CLUSTER_ENDPOINT")
    .token("YOUR_CLUSTER_TOKEN");
let client = ClientV2::new(&config).await?;

let schema = CollectionSchema::new()
    .add_field(
        FieldSchema::new()
            .name("id")
            .data_type(DataType::Int64)
            .primary_key(true),
    )
    .add_field(
        FieldSchema::new()
            .name("vector")
            .data_type(DataType::FloatVector)
            .dimension(5),
    )
    .add_field(
        FieldSchema::new()
            .name("my_varchar")
            .data_type(DataType::VarChar)
            .max_length(512)
            .partition_key(true), // Add the partition key
    );
#include "milvus/MilvusClientV2.h"

auto client = milvus::MilvusClientV2::Create();

milvus::ConnectParam connect_param{"YOUR_CLUSTER_ENDPOINT", "YOUR_CLUSTER_TOKEN"};
auto status = client->Connect(connect_param);
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}

milvus::CollectionSchemaPtr schema = std::make_shared<milvus::CollectionSchema>();
schema->AddField({"id", milvus::DataType::INT64, "", true, false});
schema->AddField(milvus::FieldSchema("vector", milvus::DataType::FLOAT_VECTOR).WithDimension(5));
schema->AddField(milvus::FieldSchema("my_varchar", milvus::DataType::VARCHAR).WithPartitionKey(true).WithMaxLength(512));
import { MilvusClient, DataType } from "@zilliz/milvus2-sdk-node";

const address = "YOUR_CLUSTER_ENDPOINT";
const token = "YOUR_CLUSTER_TOKEN";
const client = new MilvusClient({address, token});

// Define fields
const fields = [
  {
    name: 'id',
    data_type: DataType.Int64,
    is_primary_key: true,
  },
  {
    name: 'vector',
    data_type: DataType.FloatVector,
    dim: 5,
  },
  {
    name: 'my_varchar',
    data_type: DataType.VarChar,
    max_length: 512,
    is_partition_key: true,
  },
];
using Milvus.Client.V2;
using Milvus.Client.V2.Types;

var config = new ConnectConfig
{
    Uri = "YOUR_CLUSTER_ENDPOINT",
    ApiKey = "YOUR_CLUSTER_TOKEN"
};
using var client = new MilvusClientV2(config);
await client.ConnectAsync();

var schema = new CollectionSchema
{
    Fields =
    {
        new FieldSchema("id", DataType.Int64, isPrimaryKey: true),
        FieldSchema.CreateFloatVector("vector", dimension: 5),
        // Add the partition key
        FieldSchema.CreateVarchar("my_varchar", maxLength: 512, isPartitionKey: true)
    }
};
export schema='{
        "autoId": true,
        "enabledDynamicField": false,
        "fields": [
            {
                "fieldName": "id",
                "dataType": "Int64",
                "isPrimary": true
            },
            {
                "fieldName": "vector",
                "dataType": "FloatVector",
                "elementTypeParams": {
                    "dim": "5"
                }
            },
            {
                "fieldName": "my_varchar",
                "dataType": "VarChar",
                "isPartitionKey": true,
                "elementTypeParams": {
                    "max_length": 512
                }
            }
        ]
    }'
Set Partition Numbers
When you designate a scalar field in a collection as the Partition Key, Zilliz Cloud automatically creates 16 partitions in the collection. Upon receiving an entity, Zilliz Cloud chooses a partition based on the Partition Key value of this entity and stores the entity in the partition, resulting in some or all partitions holding entities with different Partition Key values.
You can also determine the number of partitions to create along with the collection. This is valid only if you have a scalar field designated as the Partition Key.
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- CSharp
- cURL
client.create_collection(
    collection_name="my_collection",
    schema=schema,
    num_partitions=128
)
import io.milvus.v2.service.collection.request.CreateCollectionReq;

CreateCollectionReq createCollectionReq = CreateCollectionReq.builder()
                .collectionName("my_collection")
                .collectionSchema(schema)
                .numPartitions(128)
                .build();
        client.createCollection(createCollectionReq);
err = client.CreateCollection(ctx,
    milvusclient.NewCreateCollectionOption("my_collection", schema).
        WithNumPartitions(128))
if err != nil {
    fmt.Println(err.Error())
    // handle error
}
use milvus::v2::prelude::*;

client.create_collection(
    CreateCollectionRequest::builder()
        .collection_name("my_collection")
        .schema(schema)
        .num_partitions(128)
        .build()?,
)
.await?;
#include <iostream>
#include "milvus/MilvusClientV2.h"

status = client->CreateCollection(milvus::CreateCollectionRequest()
                                      .WithCollectionName("my_collection")
                                      .WithCollectionSchema(schema)
                                      .WithNumPartitions(128));
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
await client.create_collection({
    collection_name: "my_collection",
    fields: fields,
    num_partitions: 128
})
using Milvus.Client.V2.Requests.Collection;

await client.CreateCollectionAsync(new CreateCollectionReq
{
    CollectionName = "my_collection",
    Schema = schema,
    NumPartitions = 128
});
export params='{
    "partitionsNum": 128
}'

export CLUSTER_ENDPOINT="YOUR_CLUSTER_ENDPOINT"
export TOKEN="YOUR_CLUSTER_TOKEN"

curl --request POST \
--url "${CLUSTER_ENDPOINT}/v2/vectordb/collections/create" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
--header "Request-Timeout: 10" \
-d "{
    \"collectionName\": \"my_collection\",
    \"schema\": $schema,
    \"params\": $params
}"
Create Filtering Condition
When conducting ANN searches in a collection with the Partition Key feature enabled, you need to include a filtering expression involving the Partition Key in the search request. In the filtering expression, you can restrict the Partition Key value within a specific range so that Zilliz Cloud restricts the search scope within the corresponding partitions.
When performing delete operations, It is advisable to include a filter expression that specifies a single partition key to achieve more efficient deletion. This approach limits the delete operation to a particular partition, reducing write amplification during compaction and conserving resources for compaction and indexing.
The following examples demonstrate Partition-Key-based filtering based on a specific Partition Key value and a set of Partition Key values.
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- CSharp
- cURL
# Filter based on a single partition key value, or
filter='partition_key == "x" && <other conditions>'

# Filter based on multiple partition key values
filter='partition_key in ["x", "y", "z"] && <other conditions>'
// Filter based on a single partition key value, or
String filter = "partition_key == 'x' && <other conditions>";

// Filter based on multiple partition key values
filter = "partition_key in ['x', 'y', 'z'] && <other conditions>";
// Filter based on a single partition key value, or
filter := "partition_key == 'x' && <other conditions>"

// Filter based on multiple partition key values
filter = "partition_key in ['x', 'y', 'z'] && <other conditions>"
// Filter based on a single partition key value, or
let filter = "partition_key == 'x' && <other conditions>";

// Filter based on multiple partition key values
let filter = "partition_key in ['x', 'y', 'z'] && <other conditions>";
// Filter based on a single partition key value, or
std::string filter = R"(partition_key == 'x' && <other conditions>)";

// Filter based on multiple partition key values
filter = R"(partition_key in ['x', 'y', 'z'] && <other conditions>)";
// Filter based on a single partition key value, or
const filter = 'partition_key == "x" && <other conditions>'

// Filter based on multiple partition key values
filter = 'partition_key in ["x", "y", "z"] && <other conditions>'
// Filter based on a single partition key value, or
string filter = "partition_key == 'x' && <other conditions>";

// Filter based on multiple partition key values
filter = "partition_key in ['x', 'y', 'z'] && <other conditions>";
# Filter based on a single partition key value, or
export filter='partition_key == "x" && <other conditions>'

# Filter based on multiple partition key values
export filter='partition_key in ["x", "y", "z"] && <other conditions>'
You have to replace partition_key with the name of the field that is designated as the partition key.
Index Partition Key
We recommend that you create a scalar index on the Partition Key field.
The Partition Key narrows a search down to the partitions that may hold the matching Partition Key values. However, each partition usually holds entities with many different Partition Key values, so Zilliz Cloud still evaluates the Partition-Key-based filter against every entity in the partitions it searches. Without a scalar index on the field, that evaluation is a full scan of the field values, which can take up a large share of search latency on large collections. With a scalar index, Zilliz Cloud looks up the matching entities in the index instead.
This evaluation happens regardless of the vector index type. Zilliz Cloud can embed Partition Key values into HNSW-family vector indexes so that a Partition-Key-filtered search traverses only the relevant sub-indexes, but that optimization narrows the vector traversal — it does not remove the filter evaluation. Searches that filter on scalar fields alone have no equivalent shortcut. In both cases, a scalar index on the Partition Key field is what keeps the evaluation fast.
Choose the index type based on the Partition Key field:
-
INVERTED suits most Partition Key fields, because Partition-Key-based filters use
==andinconditions. -
BITMAP suits fields with few distinct values. As a general guideline, use it only when the field holds fewer than 500 distinct values.
-
STL_SORT is an alternative for numeric and
VARCHARfields.
The following examples add an INVERTED index on the Partition Key field to the index parameters of the collection, alongside the index on the vector field.
- Python
- Java
- Go
- NodeJS
- cURL
index_params = client.prepare_index_params()

index_params.add_index(
    field_name="vector",
    index_type="AUTOINDEX",
    metric_type="COSINE"
)

# Index the partition key
index_params.add_index(
    field_name="my_varchar",
    index_type="INVERTED"
)

client.create_index(
    collection_name="my_collection",
    index_params=index_params
)
import io.milvus.v2.common.IndexParam;
import io.milvus.v2.service.index.request.CreateIndexReq;
import java.util.*;

List<IndexParam> indexParams = new ArrayList<>();
indexParams.add(IndexParam.builder()
        .fieldName("vector")
        .indexType(IndexParam.IndexType.AUTOINDEX)
        .metricType(IndexParam.MetricType.COSINE)
        .build());

// Index the partition key
indexParams.add(IndexParam.builder()
        .fieldName("my_varchar")
        .indexType(IndexParam.IndexType.INVERTED)
        .build());

client.createIndex(CreateIndexReq.builder()
        .collectionName("my_collection")
        .indexParams(indexParams)
        .build());
indexOptions := []milvusclient.CreateIndexOption{
    milvusclient.NewCreateIndexOption("my_collection", "vector",
        index.NewAutoIndex(entity.COSINE)),
    // Index the partition key
    milvusclient.NewCreateIndexOption("my_collection", "my_varchar",
        index.NewInvertedIndex()),
}

for _, opt := range indexOptions {
    indexTask, err := client.CreateIndex(ctx, opt)
    if err != nil {
        fmt.Println(err.Error())
        // handle error
    }
    err = indexTask.Await(ctx)
}
const index_params = [{
    collection_name: "my_collection",
    field_name: "vector",
    index_type: "AUTOINDEX",
    metric_type: "COSINE"
},{
    collection_name: "my_collection",
    // Index the partition key
    field_name: "my_varchar",
    index_type: "INVERTED"
}]

await client.createIndex(index_params)
export CLUSTER_ENDPOINT="YOUR_CLUSTER_ENDPOINT"
export TOKEN="YOUR_CLUSTER_TOKEN"

export indexParams='[
        {
            "fieldName": "vector",
            "metricType": "COSINE",
            "indexName": "vector",
            "indexType": "AUTOINDEX"
        },
        {
            "fieldName": "my_varchar",
            "indexName": "my_varchar",
            "indexType": "INVERTED"
        }
    ]'

curl --request POST \
--url "${CLUSTER_ENDPOINT}/v2/vectordb/indexes/create" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
--header "Request-Timeout: 10" \
-d "{
    \"collectionName\": \"my_collection\",
    \"indexParams\": $indexParams
}"
Pass these index parameters when you create the collection, or create the index on an existing collection. For details, refer to Create Collection.
Use Partition Key Isolation
In the multi-tenancy scenario, you can designate the scalar field related to tenant identities as the partition key and create a filter based on a specific value in this scalar field. To further improve search performance in similar scenarios, Zilliz Cloud introduces the Partition Key Isolation feature.
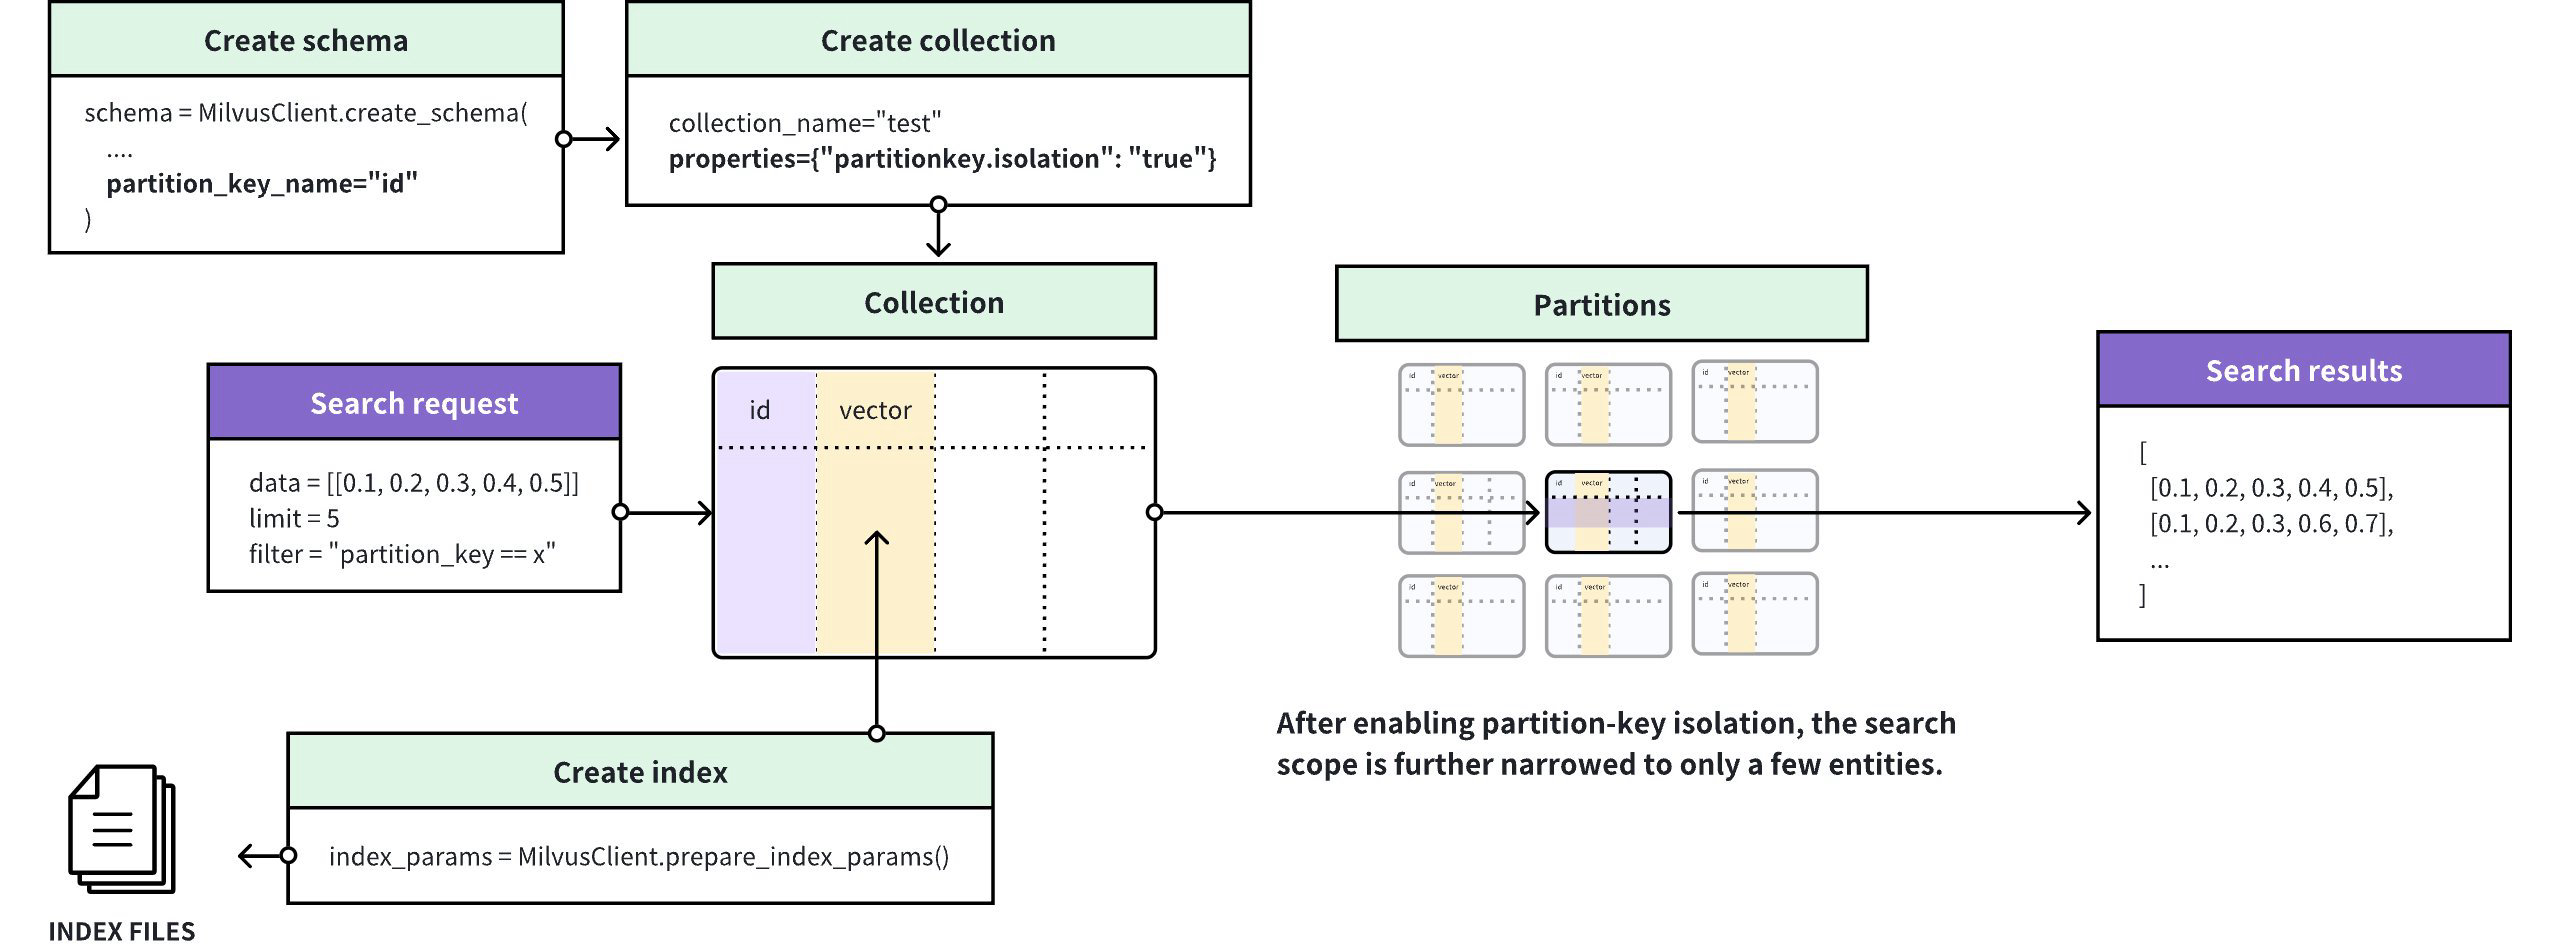
As shown in the above figure, Zilliz Cloud groups entities based on the Partition Key value and creates a separate index for each of these groups. Upon receiving a search request, Zilliz Cloud locates the index based on the Partition Key value specified in the filtering condition and restricts the search scope within the entities included in the index, thus avoiding scanning irrelevant entities during the search and greatly enhancing the search performance.
Once you have enabled Partition Key Isolation, you must include only one specific value in the Partition-key-based filter so that Zilliz Cloud can restrict the search scope within the entities included in the index that match.
Currently, the Partition-Key Isolation feature applies only to searches with the index type set to HNSW.
Partition Key Isolation does not replace the scalar index on the Partition Key field. The Partition Key value in the filter locates the matching sub-index, but Zilliz Cloud still evaluates the filter itself to identify the matching entities, so we recommend that you also index the Partition Key.
Enable Partition Key Isolation
The following code examples demonstrate how to enable Partition Key Isolation.
- Python
- Java
- Go
- Rust
- C++
- NodeJS
- CSharp
- cURL
client.create_collection(
    collection_name="my_collection",
    schema=schema,
    properties={"partitionkey.isolation": True}
)
import io.milvus.v2.service.collection.request.CreateCollectionReq;

Map<String, String> properties = new HashMap<>();
properties.put("partitionkey.isolation", "true");

CreateCollectionReq createCollectionReq = CreateCollectionReq.builder()
        .collectionName("my_collection")
        .collectionSchema(schema)
        .properties(properties)
        .build();
client.createCollection(createCollectionReq);
err = client.CreateCollection(ctx,
    milvusclient.NewCreateCollectionOption("my_collection", schema).
        WithProperty("partitionkey.isolation", true))
if err != nil {
    fmt.Println(err.Error())
    // handle error
}
use milvus::v2::prelude::*;
use std::collections::HashMap;

client.create_collection(
    CreateCollectionRequest::builder()
        .collection_name("my_collection")
        .schema(schema)
        .properties(HashMap::from([(
            "partitionkey.isolation".to_string(),
            "true".to_string(),
        )]))
        .build()?,
)
.await?;
#include <iostream>
#include "milvus/MilvusClientV2.h"

status = client->CreateCollection(milvus::CreateCollectionRequest()
                                      .WithCollectionName("my_collection")
                                      .WithCollectionSchema(schema)
                                      .AddProperty("partitionkey.isolation", "true"));
if (!status.IsOk()) {
    std::cout << status.Message() << std::endl;
}
await client.alterCollectionProperties({
    collection_name: "my_collection",
    properties: {
        "partitionkey.isolation": true
    }
})
using Milvus.Client.V2.Requests.Collection;

await client.CreateCollectionAsync(new CreateCollectionReq
{
    CollectionName = "my_collection",
    Schema = schema,
    Properties = { ["partitionkey.isolation"] = "true" }
});
export params='{
    "partitionKeyIsolation": true
}'

export CLUSTER_ENDPOINT="YOUR_CLUSTER_ENDPOINT"
export TOKEN="YOUR_CLUSTER_TOKEN"

curl --request POST \
--url "${CLUSTER_ENDPOINT}/v2/vectordb/collections/create" \
--header "Authorization: Bearer ${TOKEN}" \
--header "Content-Type: application/json" \
--header "Request-Timeout: 10" \
-d "{
    \"collectionName\": \"my_collection\",
    \"schema\": $schema,
    \"params\": $params
}"
Once you have enabled Partition Key Isolation, you can still set the Partition Key and number of partitions as described in Set Partition Numbers. Note that the Partition-Key-based filter should include only a specific Partition Key value.